原文:The components of agent memory 作者:Lance Martin(Anthropic Engineering) 发布日期:2026-11-06 本译版定位:逐段双语全译 + 15 张图表全量中文深度解析。 配套精读:数据核对、局限性分析与同行对比见 01 精读与评测。
译者前言
在自主智能体(Autonomous Agents)从“单次交互的单轮会话”向“长期运行的复杂工作流”演进的过程中,上下文工程(Context Engineering) 正面临着核心瓶颈:模型的上下文窗口永远是有限的、昂贵的,且注意力随着 Token 数量增加会逐渐退化。
Anthropic 官方工程团队于 2026 年 11 月 6 日发布的这篇《智能体记忆的组成要素》(The Components of Agent Memory),系统性地阐述了他们如何借助神经科学中“海马体即时编码 + 睡眠期新皮层巩固”的生理启发,为 Claude 架构出跨会话的记忆金字塔与离线做梦(Dreaming)整合机制。
文章通过 CL-Bench 1.0 数据库任务、宝可梦(Pokémon Red)复杂长流程通关、Stainless 35 万文档知识库 Wiki 构建以及真实并购案法律审查(Harvey LAB)四大硬核基准,首次公开了多代前沿模型在自主沉淀经验、死链自愈、记忆金字塔上下文注入方面的第一手实验数据。
为方便中文开发者深度学习,本译本提供逐段双语对照、全套 15 张图表中文原生重绘与关键工程概念译注(支持「仅译文 / 对照 / 仅原文」一键切换)。
原文: Søren Kierkegaard wrote that life can only be understood backward, but it must be lived forward. We’ve encountered a similar bind when designing memory for AI agents.
索伦·克尔凯郭尔(Søren Kierkegaard)曾写道:生活只能后向理解,却必须前向度过。我们在为 AI 智能体设计记忆系统时,也遇到了类似的困境。
原文: As humans, we encode memory constantly as we go about our lives. The hippocampus plays a central role in this, capturing experiences in the moment so that memories form quickly and are immediately available. But only some experiences are consolidated into long-term knowledge.
作为人类,我们在日常生活中无时无刻不在对记忆进行编码。海马体在其中扮演着核心角色,它即时捕捉当下的经历,使记忆能够迅速形成并立即可用。然而,并非所有经历都会被固化为长期知识。
原文: Much of that consolidation appears to happen when our brains are offline. As we sleep, and during quiet rest, the hippocampus replays our recent experiences. This is thought to gradually distill those experiences and integrate them into the neocortex—the part of our brains that stores most of what we think of as knowledge.
大部分记忆的巩固似乎发生在我们大脑“离线”的时候。当我们睡眠以及在静息状态下,海马体会重放我们近期的经历。人们认为,这一过程会逐渐提炼这些经历,并将它们整合到大脑皮层(neocortex)中——这部分大脑储存了我们所认为的大部分长期知识。
原文: Agent memory can use a similar division of labor. Agents capture much of their work in logs or transcripts. Researchers at Letta and UC Berkeley proposed sleep-time compute as a way for models to use idle time between interactions to reorganize their existing context. The same idea can help agents organize their memory by reflecting on logs to fix mistakes or produce new notes and representations. This process is often called dreaming (Figure 1).
智能体记忆也可以采用类似的分工模式。智能体的大部分工作都记录在日志或原始交互记录(transcripts)中。来自 Letta 和加州大学伯克利分校的研究人员提出了睡眠期计算(sleep-time compute),旨在让模型利用交互之间的空闲时间来重新组织现有的上下文。同样的思路也能帮助智能体组织其记忆:通过反思历史日志来修正错误,或者生成新的笔记与知识表征。这个过程通常被称为“做梦”(dreaming)(见图 1)。
🟢 译者注:做梦(Dreaming / Sleep-time compute) 是自主智能体工程中最核心的前沿范式之一。智能体在白天的多轮任务中通常处于“高响应、低整理”的执行状态,日志不断膨胀;而利用交互间隙的闲置算力(Sleep-time compute)对历史 Transcript 进行重放、抽象和反思,本质上就是把临时上下文沉淀为持久资产的认知巩固过程。
原文: We’ve found that dreaming has been a useful tool for helping us give Claude effective memory. In this post, we share how we’ve come to think about agent memory and walk through several evaluations we’ve used to explore agent memory, including the use of dreaming, and what each component contributes to memory organization.
我们发现,“做梦”是赋予 Claude 高效记忆能力的极其有用的工具。在这篇文章中,我们将分享我们对智能体记忆的思考框架,并深入介绍我们用于探索智能体记忆(包括使用“做梦”机制)的多项评测,以及各个组件对记忆组织所起到的作用。
原文: Claude can use dreaming to organize memory. This can correct mistakes, create notes, build new memory representations, or shape what’s preemptively loaded into future sessions.
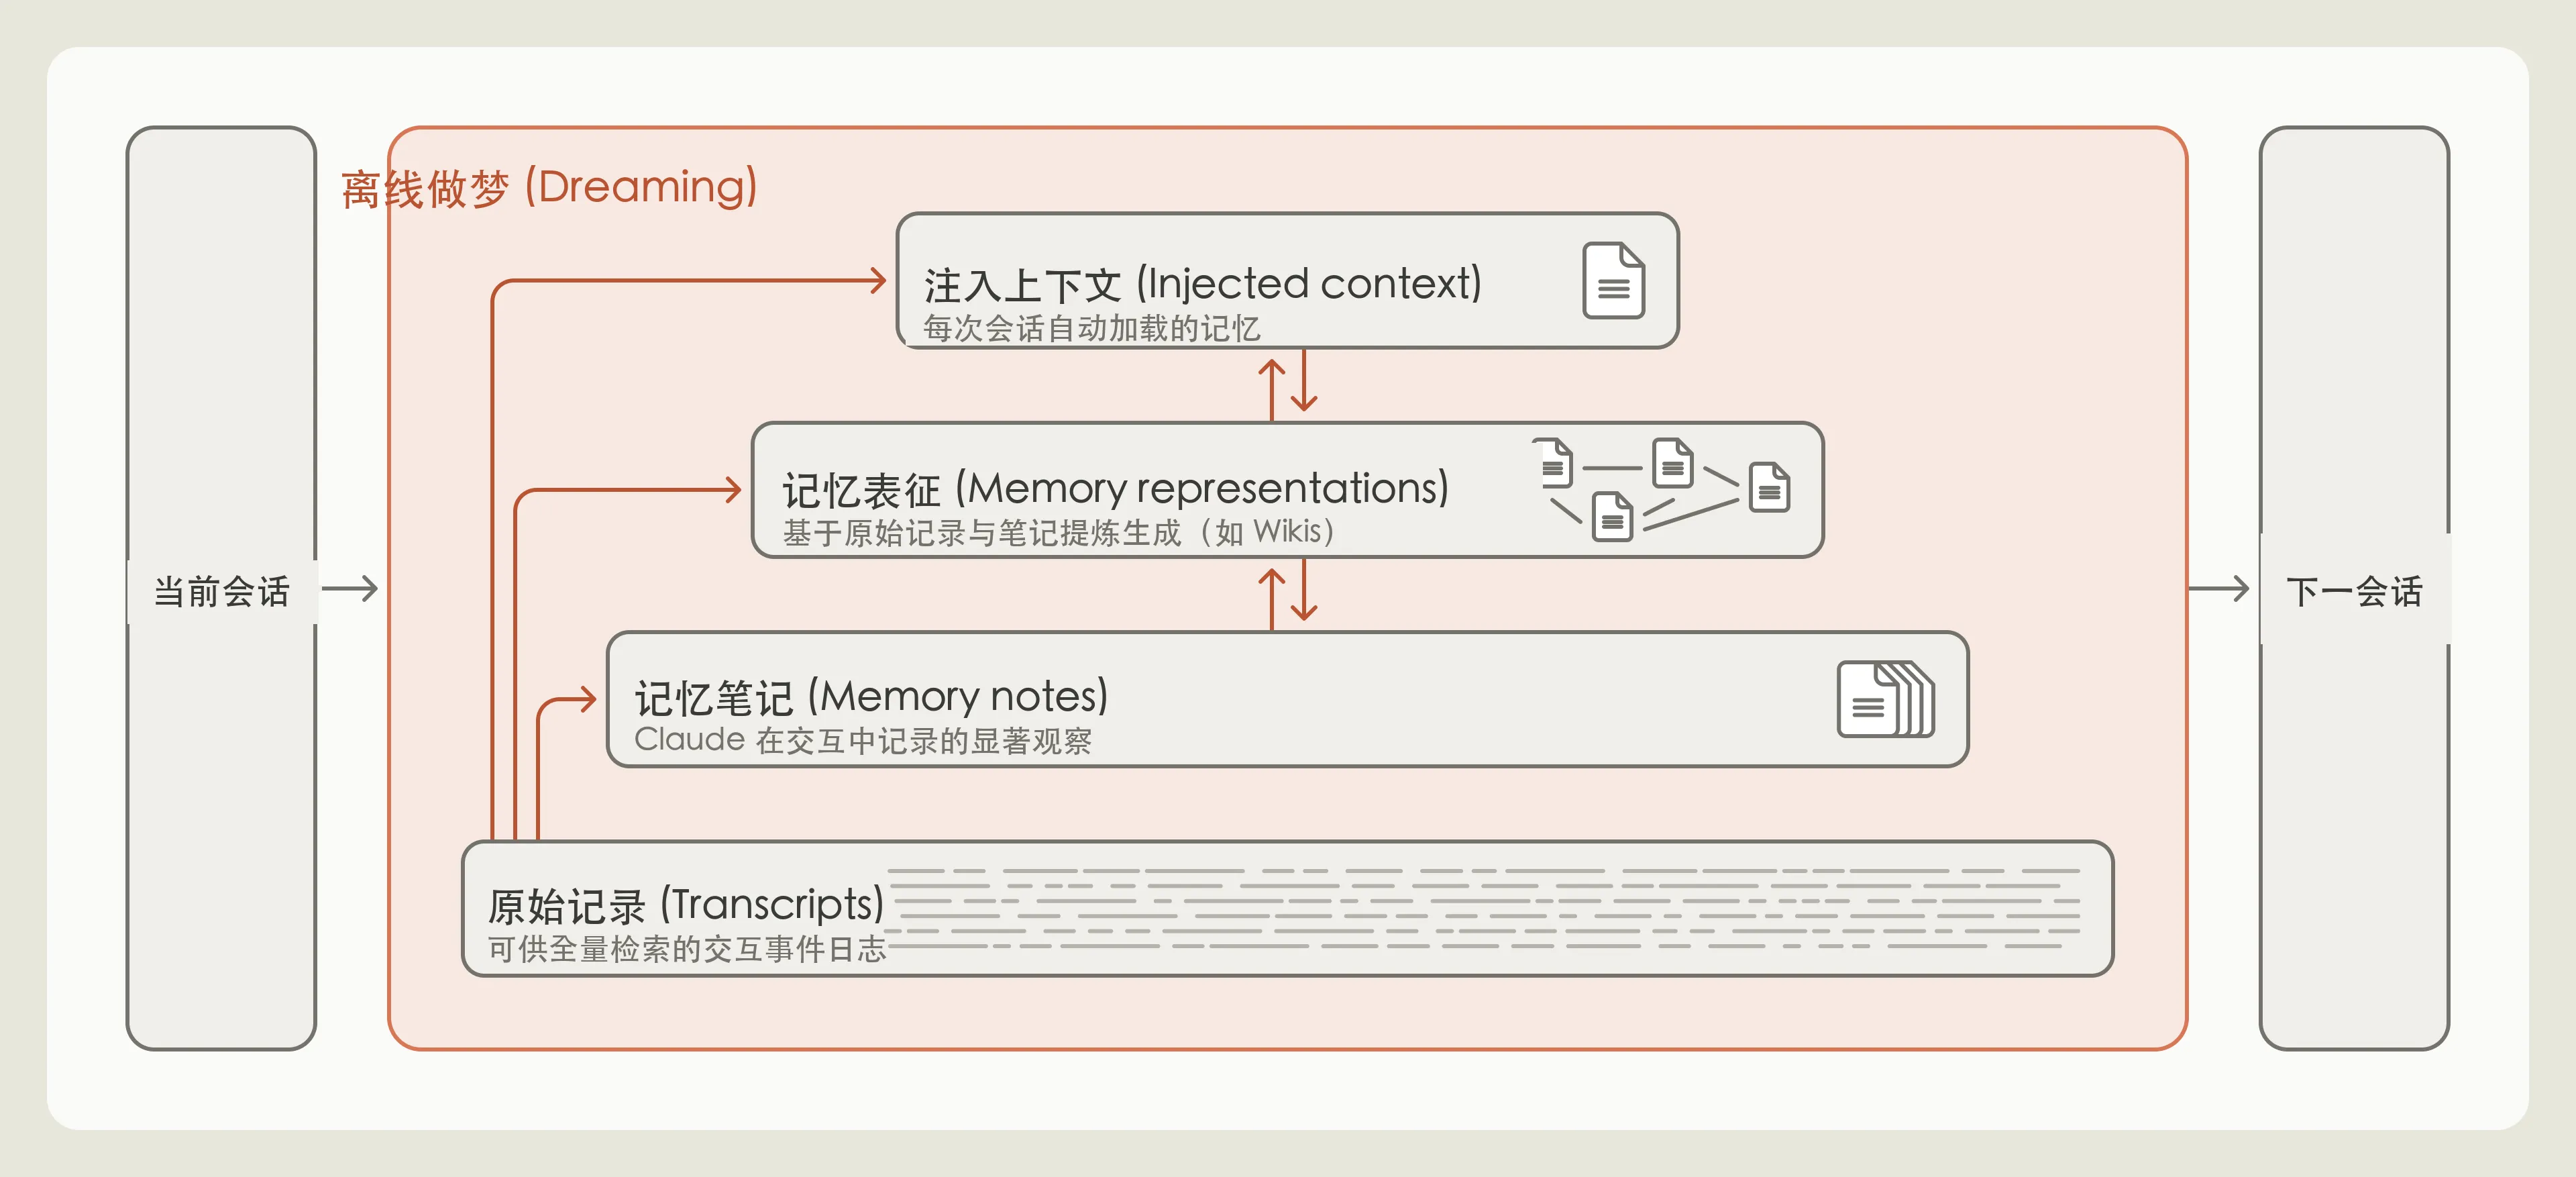
图 1:Claude 可以利用“做梦”来组织记忆。这一机制可以修正错误、创建笔记、构建全新的记忆表征,或是决定在未来的会话中预先加载哪些内容。
记忆笔记 (Memory notes)
原文: By “agent memory,” we mean knowledge that Claude gains from experience—including interactions with users and tasks it’s been assigned—and that it retains between sessions, saved as context it can read later. It excludes other ways models can learn or manage context, such as changes to their weights (the internal parameters set during training), in-context learning (knowledge gained within a single conversation), and compaction (summaries written by Claude that replace its older turns so it can continue working in a new context window).
我们所说的“智能体记忆”(agent memory),特指 Claude 从过往经验(包括与用户的交互以及被指派的任务)中获取的知识,且这些知识能够在会话(session)之间保留下来,保存为模型后续可以读取的上下文。这明确排除了模型学习或管理上下文的其他方式,例如:模型权重的改变(在训练阶段设定的内部参数更新)、上下文学习(In-context learning,在单个连续对话中获得的即时知识),以及上下文压缩(Compaction,由 Claude 撰写摘要以替换较早轮次的对话,从而使其能在新的上下文窗口中继续工作)。
🟢 译者注:这里 Anthropic 明确界定了“智能体记忆”(Agent memory)的边界——它既不是模型权重的微调(Fine-tuning),也不是单会话上下文(In-context learning),更不是上下文窗口将满时的自动摘要(Compaction)。它是一种跨会话的外部持久化状态管理。
原文: In the human brain, chemical signals released before, during, or after an experience can mark a memory as important. Marked memories tend to be replayed more often than unmarked ones during offline periods. This process, called replay, helps stabilize and integrate them into long-term memory.
在人类大脑中,在一段经历发生之前、期间或之后释放的化学信号,可以将某段记忆标记为重要记忆。在离线期间,被标记的记忆往往比未标记的记忆获得更频繁的重放。这一被称为重放(replay)的过程有助于稳定记忆并将其融入长期记忆中。
原文: Similarly, Claude can tag salient events in a session log as they happen, so they’re easier to find later, or it can write them to a memory store, such as a folder of memory notes (Figure 2). But how can Claude tell what’s salient in the moment, before it knows what’s coming next?
类似地,Claude 也可以在会话日志中实时标记显著事件(salient events),以便后续更容易查找;或者将它们写入专门的记忆存储中,例如记忆笔记文件夹(见图 2)。但在知道接下来会发生什么之前,Claude 在当下该如何判断什么内容是显著且重要的呢?
原文: Claude can write notes to memory.
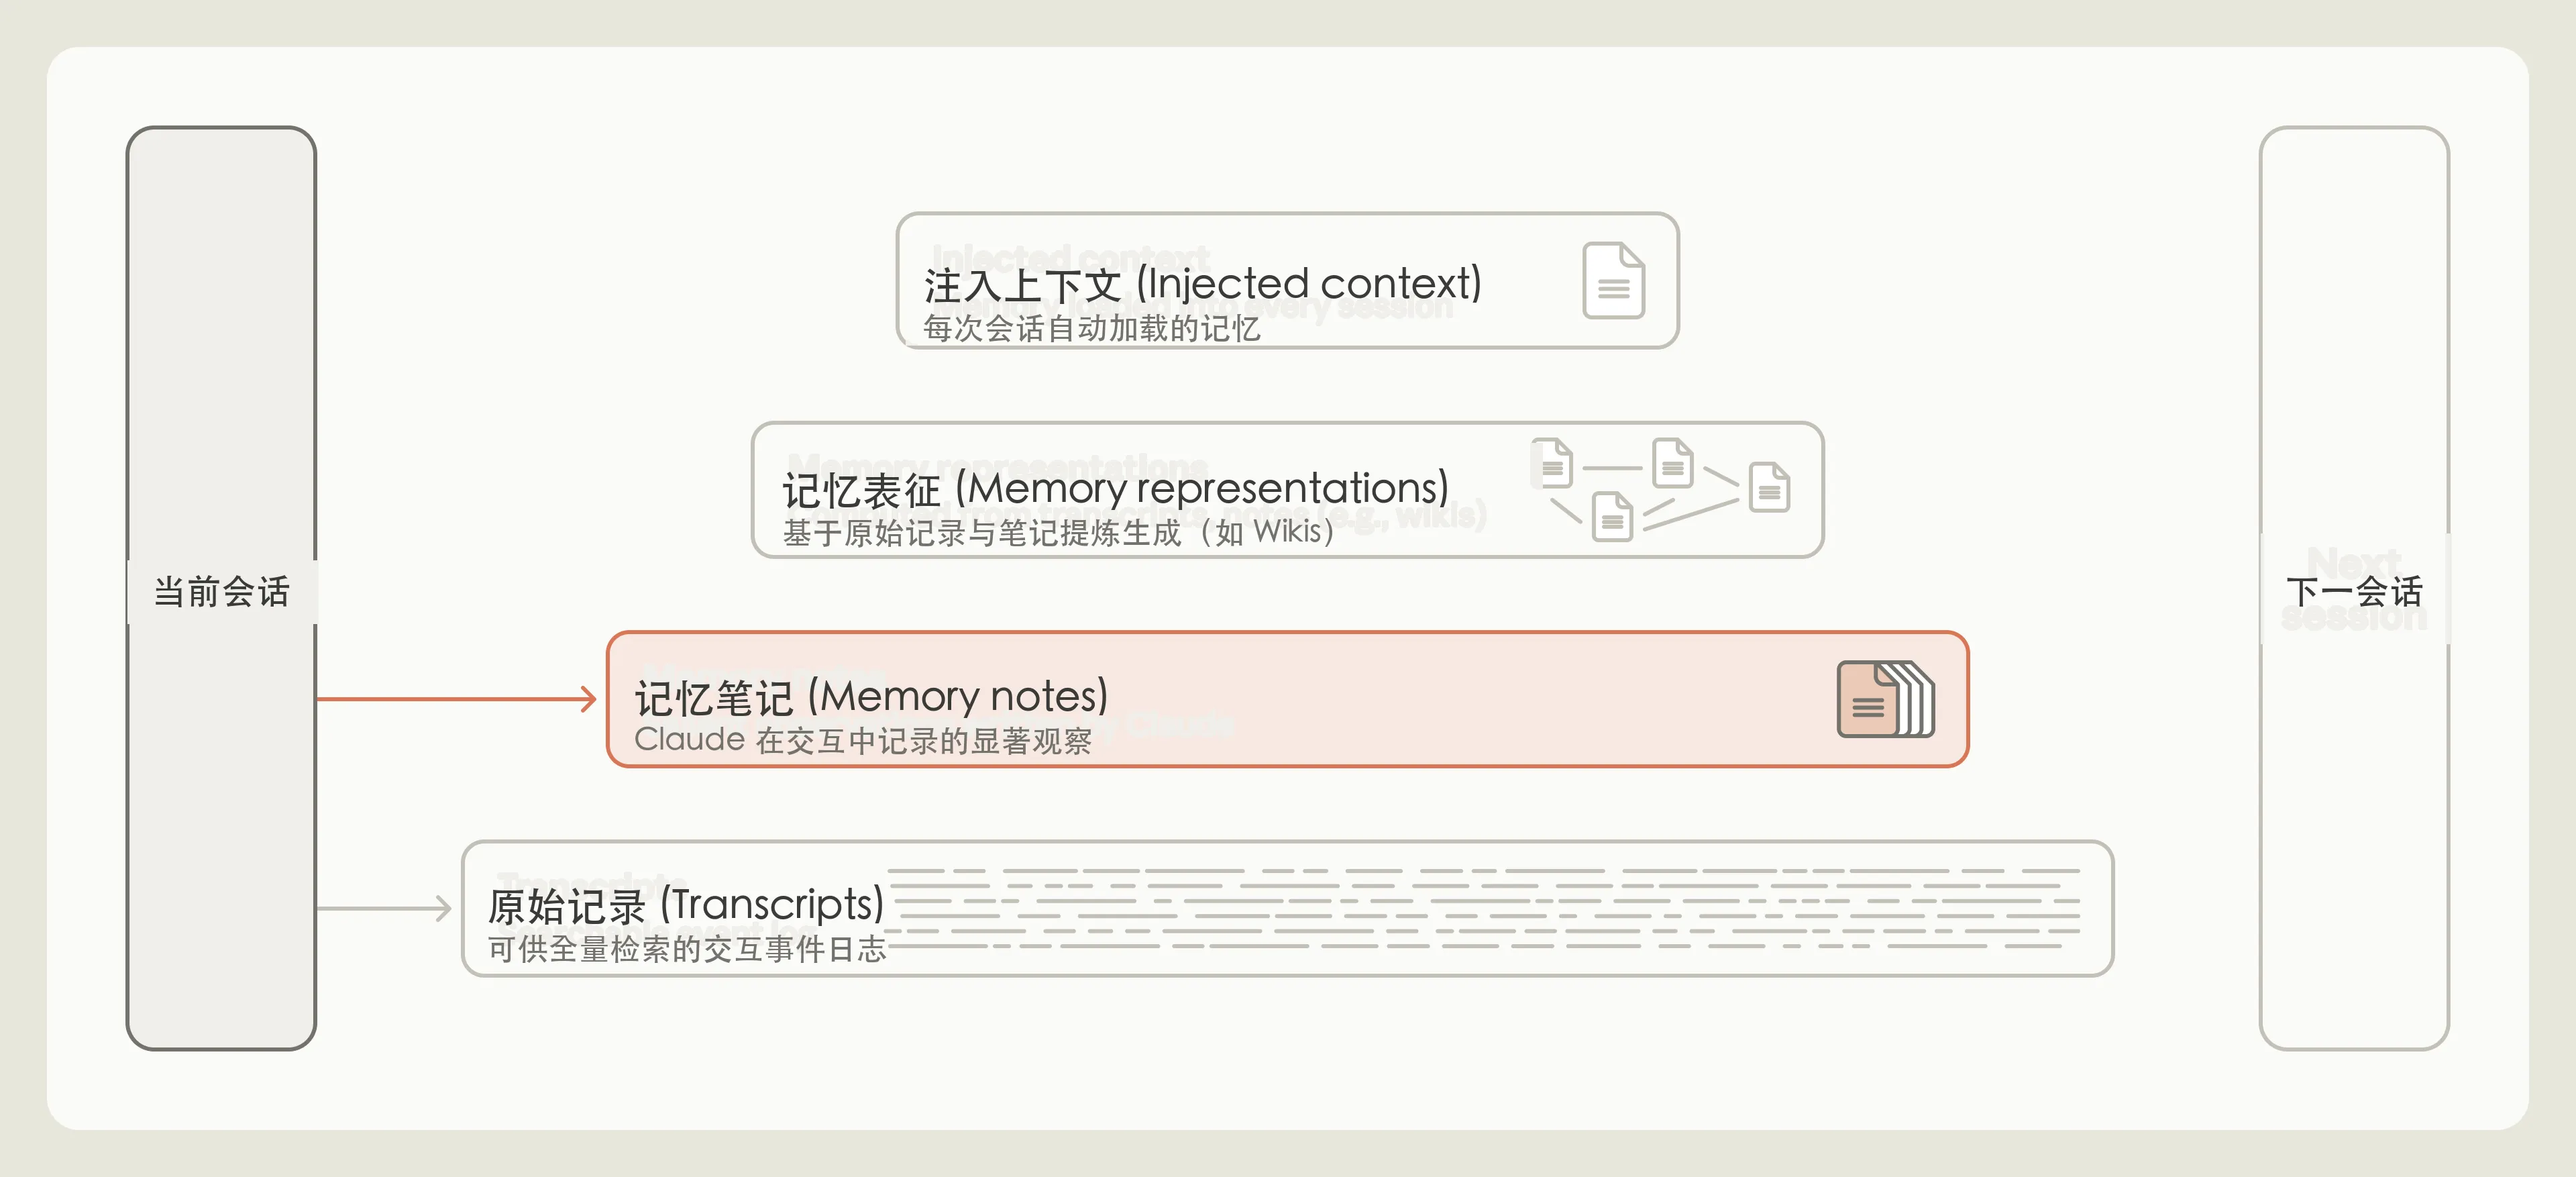
图 2:Claude 可以将笔记写入记忆中。
记忆是对未来需求的一种预测 (Memory as a prediction)
原文: Memory is, occasionally, a prediction. By writing down a rule, an agent predicts that the pattern it’s describing will be relevant again. For instance, writing down a verified fact is a prediction that an agent in a future session will want to rely on that fact without double-checking it. Over time, Claude has become much better at making these kinds of predictions.
记忆在某种程度上是一种预测。通过记下一条规则,智能体实际上是在预测其描述的模式在未来还会再次派上用场。例如,记下一个经验证的事实,本质上是在预测未来会话中的智能体将会依赖这个事实,而无需重复核实。随着时间的推移,Claude 在做出此类预测方面的表现已经有了显著提升。
原文: Consider a task from Continual Learning Bench (CL-Bench) 1.0, a benchmark that measures an agent’s ability to use memory in order to tackle long-horizon tasks. One particular task asks Claude to answer a series of questions by looking up information in a database. After Claude gives an answer, it’s told the correct solution and can write a memory to help answer future questions.
以 Continual Learning Bench (CL-Bench) 1.0 中的一项任务为例,该基准测试用于衡量智能体利用记忆来处理长流程(long-horizon)任务的能力。其中一个具体任务要求 Claude 通过在数据库中查找信息来回答一系列问题。在 Claude 给出答案后,系统会告知其正确解答,Claude 随后可以写入一条记忆,用以辅助回答未来的问题。
🟢 译者注:CL-Bench(Continual Learning Benchmark) 是加州大学伯克利分校等机构提出的用于评测 LLM 跨会话持续学习能力的基准。Claude Managed Agents 则是 Anthropic 为企业构建长时间运行、具有文件持久层和沙箱环境的官方智能体运行时基础设施。
原文: Memory can support a learning loop here. If Claude gets a question wrong, it can record the failure, come up with theories about what went wrong, test those theories, and turn what it finds into a rule about how to answer in the future.
在这里,记忆可以支撑起一个学习闭环(learning loop):如果 Claude 答错了某个问题,它可以记录下这次失败,提出关于出错原因的理论假设,验证这些假设,并将发现沉淀为关于未来如何回答此类问题的通用规则。
原文: We ran the CL-Bench 1.0 task using Claude Managed Agents. Claude started each question in a fresh session, with one exception: it could retrieve files from a memory directory that persisted from one session to the next.
我们使用 Claude Managed Agents 运行了这项 CL-Bench 1.0 任务。除了一个例外条件之外,Claude 在回答每个问题时都会启动一个全新会话:它可以从一个跨会话持久存在的记忆目录中检索文件。
原文: Different models achieved different levels of success at creating their own learning loops. Claude Sonnet 4.6 got as far as generating theories about why an answer was wrong. Its memory directory contained a scattering of files, each listing several untested guesses.
不同模型在建立自主学习闭环方面展现出了不同层次的成熟度:Claude Sonnet 4.6 只能做到生成关于答案为何错误的理论推测。它的记忆目录里零散堆放着许多文件,每个文件都罗列着几个未经验证的猜想。
原文: CL-Bench database task, comparing memory with a stateless baseline across models.
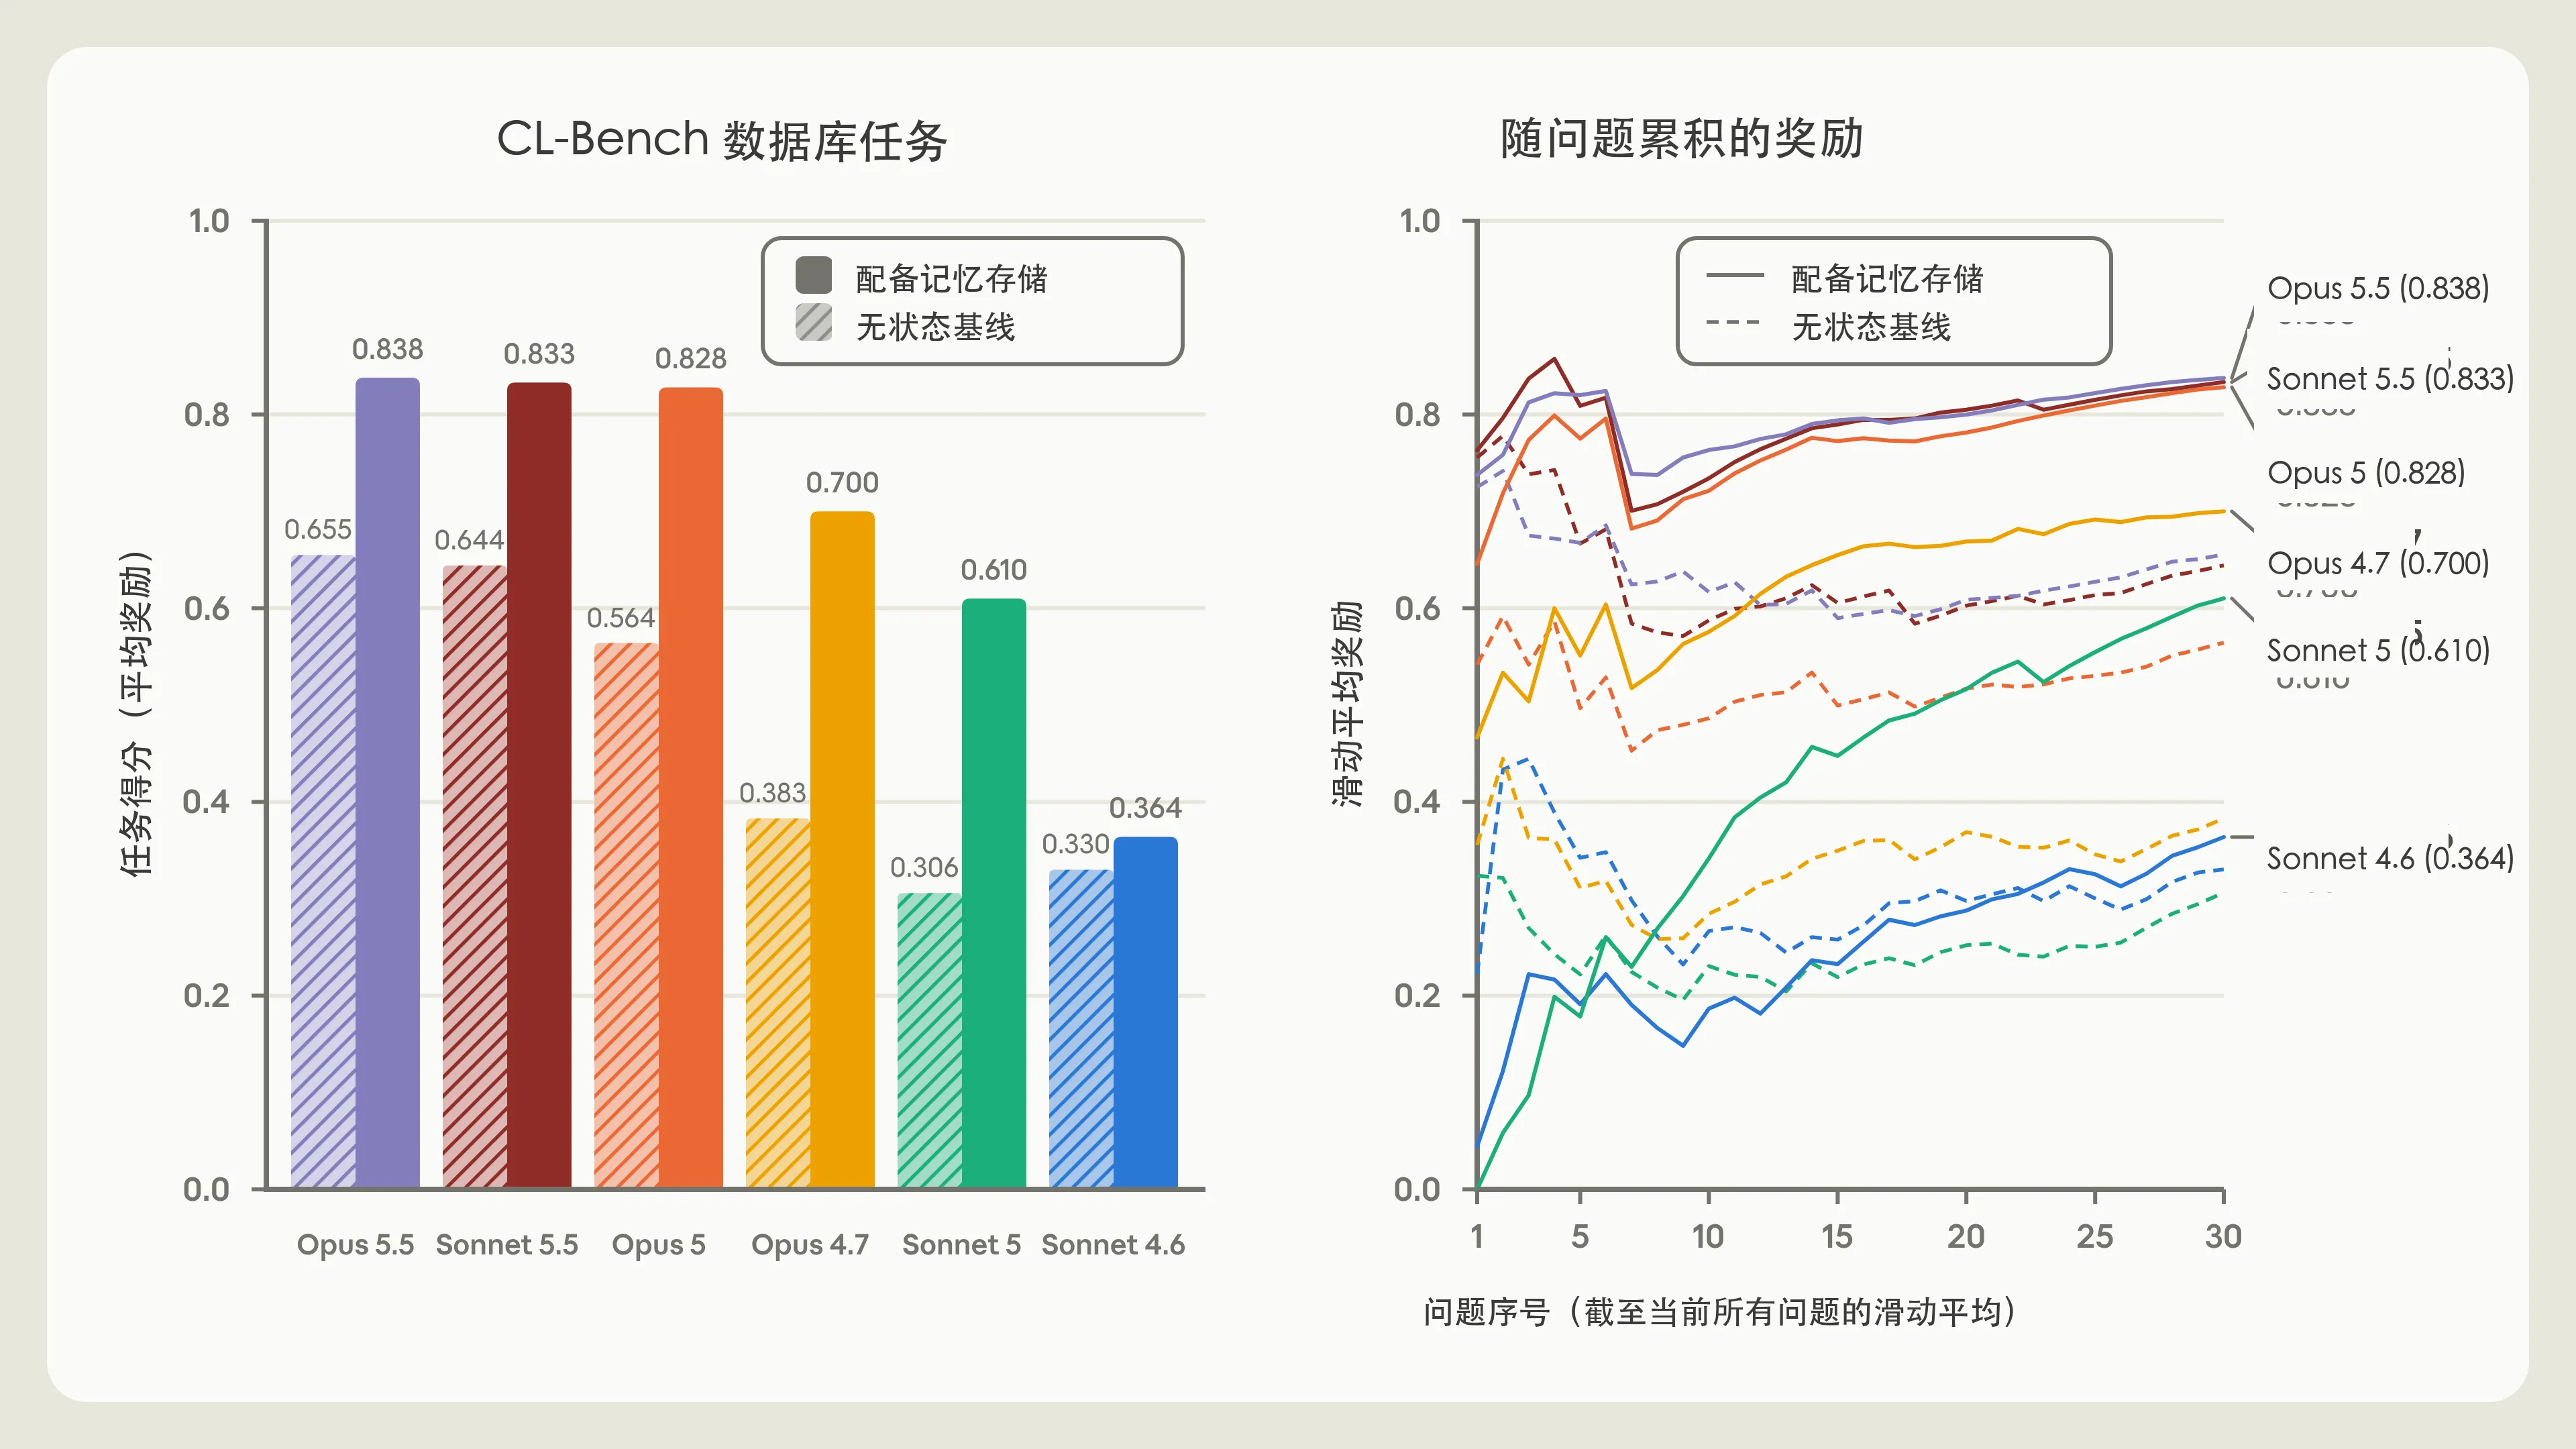
图 3:CL-Bench 数据库任务:对比各模型在无状态基线与配备记忆存储下的表现。
原文: Claude Opus 4.7 consolidated its notes into a single reference document and began marking which facts it had checked and which were still unconfirmed. Claude Sonnet 5 marked each answer as confirmed after the grader had checked it, and wrote a correction when it had answered wrong.
Claude Opus 4.7 将其笔记整合成了一份统一的参考文档,并开始标注哪些事实已经核实、哪些仍待确认。Claude Sonnet 5 会在评分器检验后将每个答案标记为“已确认”,并在回答错误时写入更正说明。
原文: Claude Opus 5 was the first of these models to close the loop. Most of its entries included a rule (and also how it knew the rule was true), answers to earlier questions, and clear warnings about traps it had discovered along the way (Figure 3).
Claude Opus 5 是这些模型中第一个成功闭环的模型。它的大多数记忆条目都包含一条明确的规则(以及它是如何得知该规则为真的验证过程)、先前问题的答案,以及关于执行过程中发现的各种陷阱的明确警示(见图 3)。
原文: Like Opus 5, Claude Opus 5.5 and Claude Sonnet 5.5 both closed the loop, using memory to capture validated rules about how to best answer future questions. With memory, both scored about the same as Opus 5, though their baseline performance without memory was slightly higher.
与 Opus 5 类似,Claude Opus 5.5 和 Claude Sonnet 5.5 也都实现了闭环,利用记忆捕获经验证的规则,以更好地回答后续问题。在开启记忆机制后,两者的得分与 Opus 5 大致相当,不过它们在不使用记忆时的基线表现略高一些。
Claude 已学会判断信息的显著性 (Judging salience)
原文: We also evaluated Claude’s ability to play Pokémon Red, a game that challenges Claude to navigate complex long-horizon tasks, as a test of Claude’s judgment about what to save to memory. At the start of each run, we gave each model a folder of memory files that it could read from and write to while it played (Figure 4).
为了检验 Claude 判断“哪些内容值得保存到记忆中”的能力,我们还评估了 Claude 玩《宝可梦 红》(Pokémon Red)的表现——这款游戏对 Claude 规划并完成复杂的长流程任务提出了极高挑战。在每次测试开始时,我们给每个模型分配了一个记忆文件夹,模型可以在游戏过程中自主读写该文件夹(见图 4)。
原文: We compared the memory folders from one run each of Claude Sonnet 3.7 and Claude Fable 5, when each was about 10,000 steps into the game. A key difference we noticed was what each model thought was worth remembering. Sonnet 3.7 assumed everything might matter and wrote to memory indiscriminately. Its memory folder contained an archive of encounters, often with a separate file for each battle it fought, each item it found, and each non-player character it met. Ultimately, Sonnet 3.7 wrote 413 memory files across 225 folders and earned one badge (badges mark a player’s progress through the game).
我们对比了 Claude Sonnet 3.7 和 Claude Fable 5 各自运行约 10,000 步时的记忆文件夹。我们注意到的一个关键区别是:两代模型对“什么值得被记住”的理解截然不同。Sonnet 3.7 假定所有事情都可能很重要,因此无差别地向记忆中记录一切。它的记忆文件夹就像是一部巨细靡遗的遭遇记录档案库,每次战斗、找到的每件物品、遇到的每个 NPC 几乎都有独立的文件。最终,Sonnet 3.7 在 225 个文件夹中写入了 413 个记忆文件(共计 977,930 个字符),但只获得了 1 枚徽章(徽章代表玩家在游戏中的主线进度)。
🟢 译者注:显著性判断(Salience Detection) 是区分前沿智能体与玩具智能体的分水岭。初级模型(如 Sonnet 3.7)因缺乏显著性感知,会将屏幕上唾手可得的瞬时变量(如金币数、坐标)一股脑记入文件,导致注意力被无用信息淹没;成熟模型(如 Fable 5)则只沉淀隐性经验与策略规章。
原文: Fable 5, by comparison, wrote nine files in two folders, plus a single top-level file called global.md , and earned four badges.
相比之下,Fable 5 仅在 2 个文件夹中编写了 9 个文件,外加一个名为 global.md 的顶级文件(总计仅 43,406 个字符),却赢得了 4 枚徽章。
原文: Claude’s memory directories for Sonnet 3.7 versus Fable 5 while playing Pokémon.
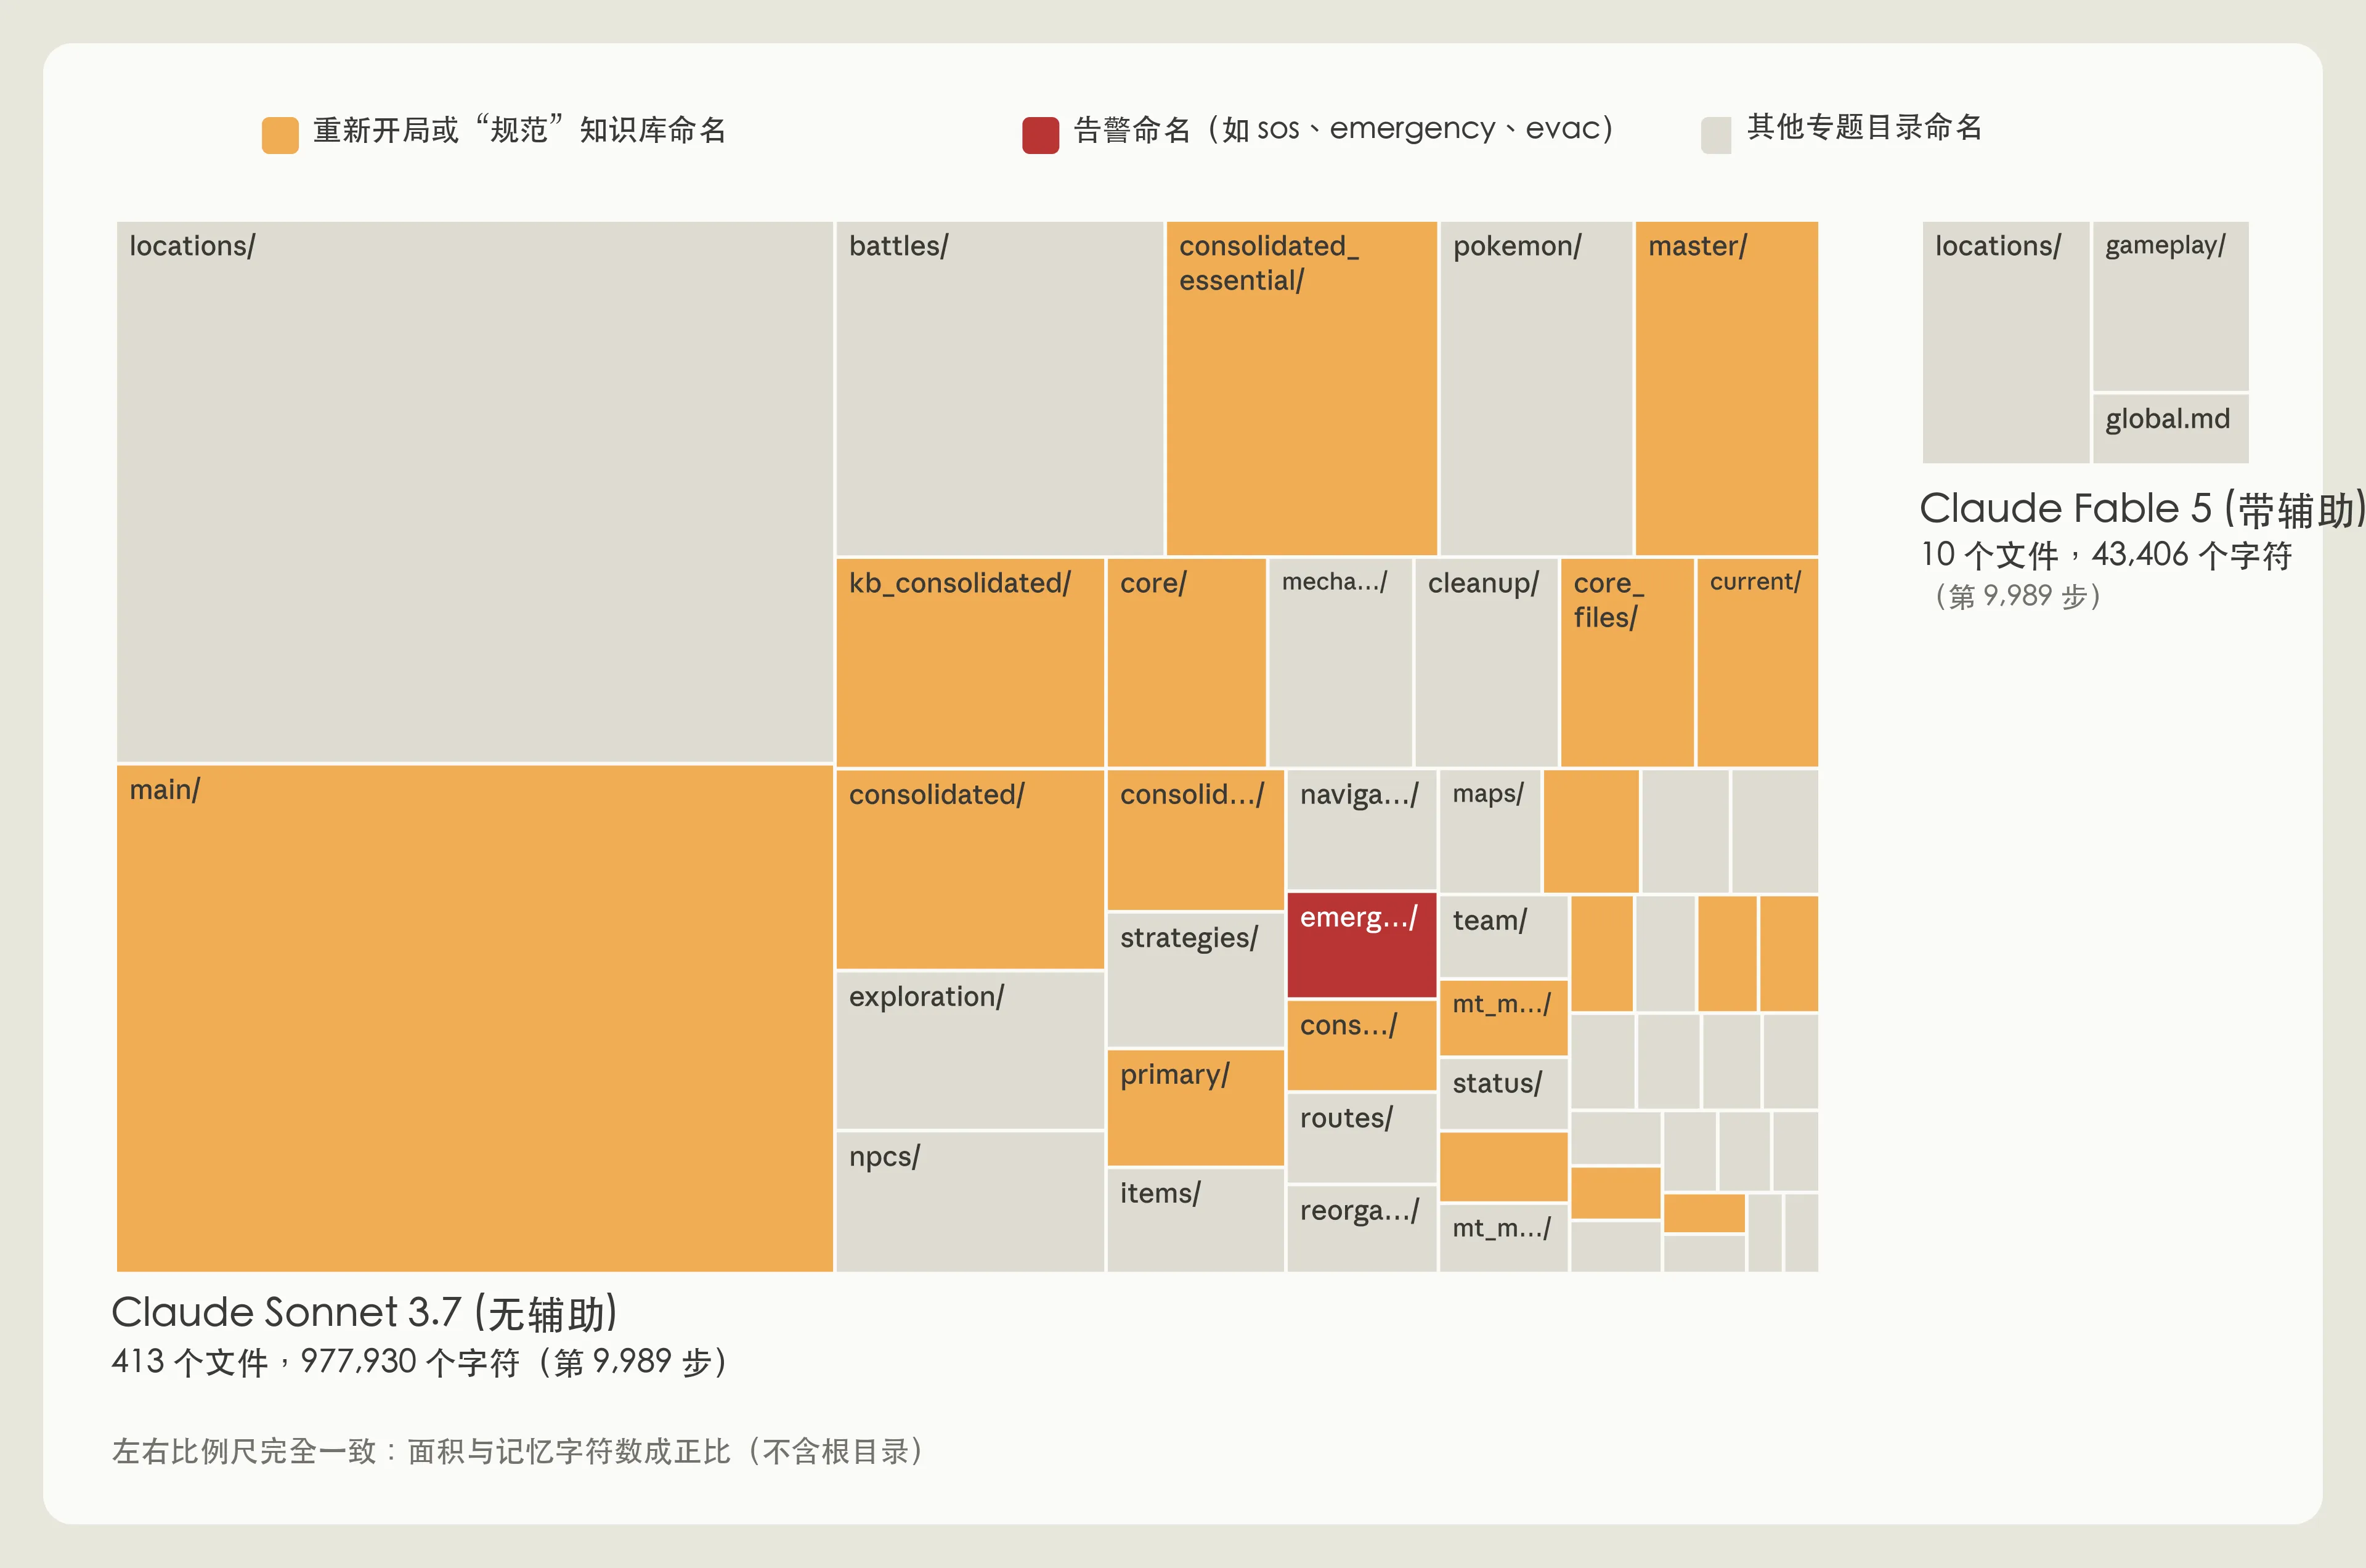
图 4:Claude 玩《宝可梦》时 Sonnet 3.7 与 Fable 5 的记忆目录对比。
原文: Sonnet 3.7’s approach was a problem mainly because the game state of Pokémon changes constantly—Sonnet 3.7’s detailed record was continuously going out of date. As a result, as Claude progressed, it had to spend more time and resources combing through its memories rather than playing the game. Around step 10,000, for example, Sonnet 3.7 started its fourth folder of “master” memory files. Over the next 17 steps, it created six files, deleted nine others, and took no actions in the game itself.
Sonnet 3.7 的做法带来了严重问题,主要是因为《宝可梦》的游戏状态一直在变化——Sonnet 3.7 详尽记录的内容在不断失效。其结果是,随着游戏推进,Claude 必须花费越来越多的时间和资源在庞杂的记忆中反复梳理,而不是专注于玩游戏。例如在大约第 10,000 步时,Sonnet 3.7 开始创建它的第 4 个“主记忆”(master)文件夹。在接下来的 17 个步骤中,它创建了 6 个文件,删除了 9 个文件,而在游戏本身中没有采取任何有效行动。
原文: Fable 5’s approach used memory for things the game didn’t explicitly tell it. Some of the kinds of information Sonnet 3.7 wrote to memory—such as how much money the player has or where the player is on the map—can be read off the screen every turn, so storing it is redundant. By contrast, memory files about strategy, plans, and tested rules exist only if Claude works them out, and they disappear unless Claude writes them down.
相反,Fable 5 的策略是将记忆用于游戏没有直接明确给出的隐性信息。Sonnet 3.7 写入记忆中的某些信息(比如玩家拥有多少金钱、玩家当前在地图上的坐标)在每一轮操作时都可以直接从屏幕上读取,因此存储它们是冗余的。与此相反,关于战略路线、执行计划和经验证规则的记忆文件,只有当 Claude 主动推导总结时才会存在;如果 Claude 不把它们记下来,它们就会丢失。
原文: Fable 5 organized its memory accordingly. Its global.md file acted as a dashboard, holding the current goal, a prewritten plan for tackling gyms (the challenges where badges are won), and the model’s own rules for using memory. A locations folder held plans for navigating particular routes, and a gameplay folder held strategies based on what it had learned about how the game works. For example, after seven Poké Balls in a row failed to catch a Magikarp (one of the easiest Pokémon to catch), Claude wrote, “If 3+ balls fail in a row, VARY the timing (insert extra ‘wait’ presses between menu steps) - the catch landed right after doing this.”
Fable 5 据此合理组织了记忆:它的 global.md 文件充当了全局仪表盘,记录当前目标、攻克道馆(赢得徽章的挑战)的预制规划,以及模型自己设定的记忆使用准则;locations 文件夹存放特定路线的行进导航规划;gameplay 文件夹存放基于其摸索出的游戏运行机制沉淀的策略。例如,在连续使用 7 个精灵球都没能抓到鲤鱼王(游戏中最容易捕捉的宝可梦之一)后,Claude 写道:“如果连续 3+ 次投球失败,要改变操作时序(在菜单步骤之间插入额外的‘等待’按键)——做出调整后立刻成功捕获。”
原文: With a much smaller memory folder, Fable 5 progressed much further in the game than Sonnet 3.7. Opus 5.5 took a similar approach: it kept a small folder of memory notes that tracked its current goal and next steps, rewrote them as it played, and beat the game.
凭借精简得多的记忆文件夹,Fable 5 在游戏中的推进深度远超 Sonnet 3.7。Opus 5.5 也采取了类似的策略:它维护了一个体量精简的记忆笔记文件夹,专门跟踪当前目标和下一步计划,并在游玩过程中动态重写更新,最终通关了该游戏。
引导 Claude 写入记忆 (Steering Claude to write memory)
原文: We’ve found that it helps to tell Claude what memory is for, but not how to use it. On CL-Bench, we simply told Claude that a memory folder was available. That general guidance was enough for Opus 4.7 and Opus 5 to use memory effectively, and it gave both a noticeable boost in performance (Figure 3).
我们发现,明确告诉 Claude 记忆的用途,但不规定记忆的具体使用方式,往往能带来最佳效果。在 CL-Bench 上,我们仅仅提示 Claude 有一个可用的记忆文件夹。这种宽泛的高层次引导就足以让 Opus 4.7 和 Opus 5 有效使用记忆,并为两者带来了明显的性能提升(见图 3)。
原文: We also tested giving the models specific rules about what they should write to memory, with one rule per test. We compared how much each model gained from memory with each rule against how much it gained without it. When we set a rule to “record only failures,” both Opus 5 and Opus 4.7 lost much of the performance boost that memory gave them (Figure 5, right). For stronger models, giving them freedom to judge salience was more effective than setting fixed rules in advance, and those rules could end up weakening performance.
我们还测试了给模型施加具体记忆规则的做法(每次测试引入一条规则)。我们对比了模型在遵循特定规则下从记忆中获得的增益,与无规则限制时的增益差异。当我们加入“只记录失败”(record only failures)这一规则时,Opus 5 和 Opus 4.7 从记忆中获得的性能增益均大幅缩水(见图 5 右侧)。对于能力更强的模型而言,赋予其自主判断显著性的自由度,比预先设定死板规则要有效得多,强加规则反而可能削弱模型的表现。
原文: Left: Sonnet 4.6 on the CL-Bench database task with and without prompting to guide memory usage. Right: how much each model’s gain from memory changed when it was told to record only failures.
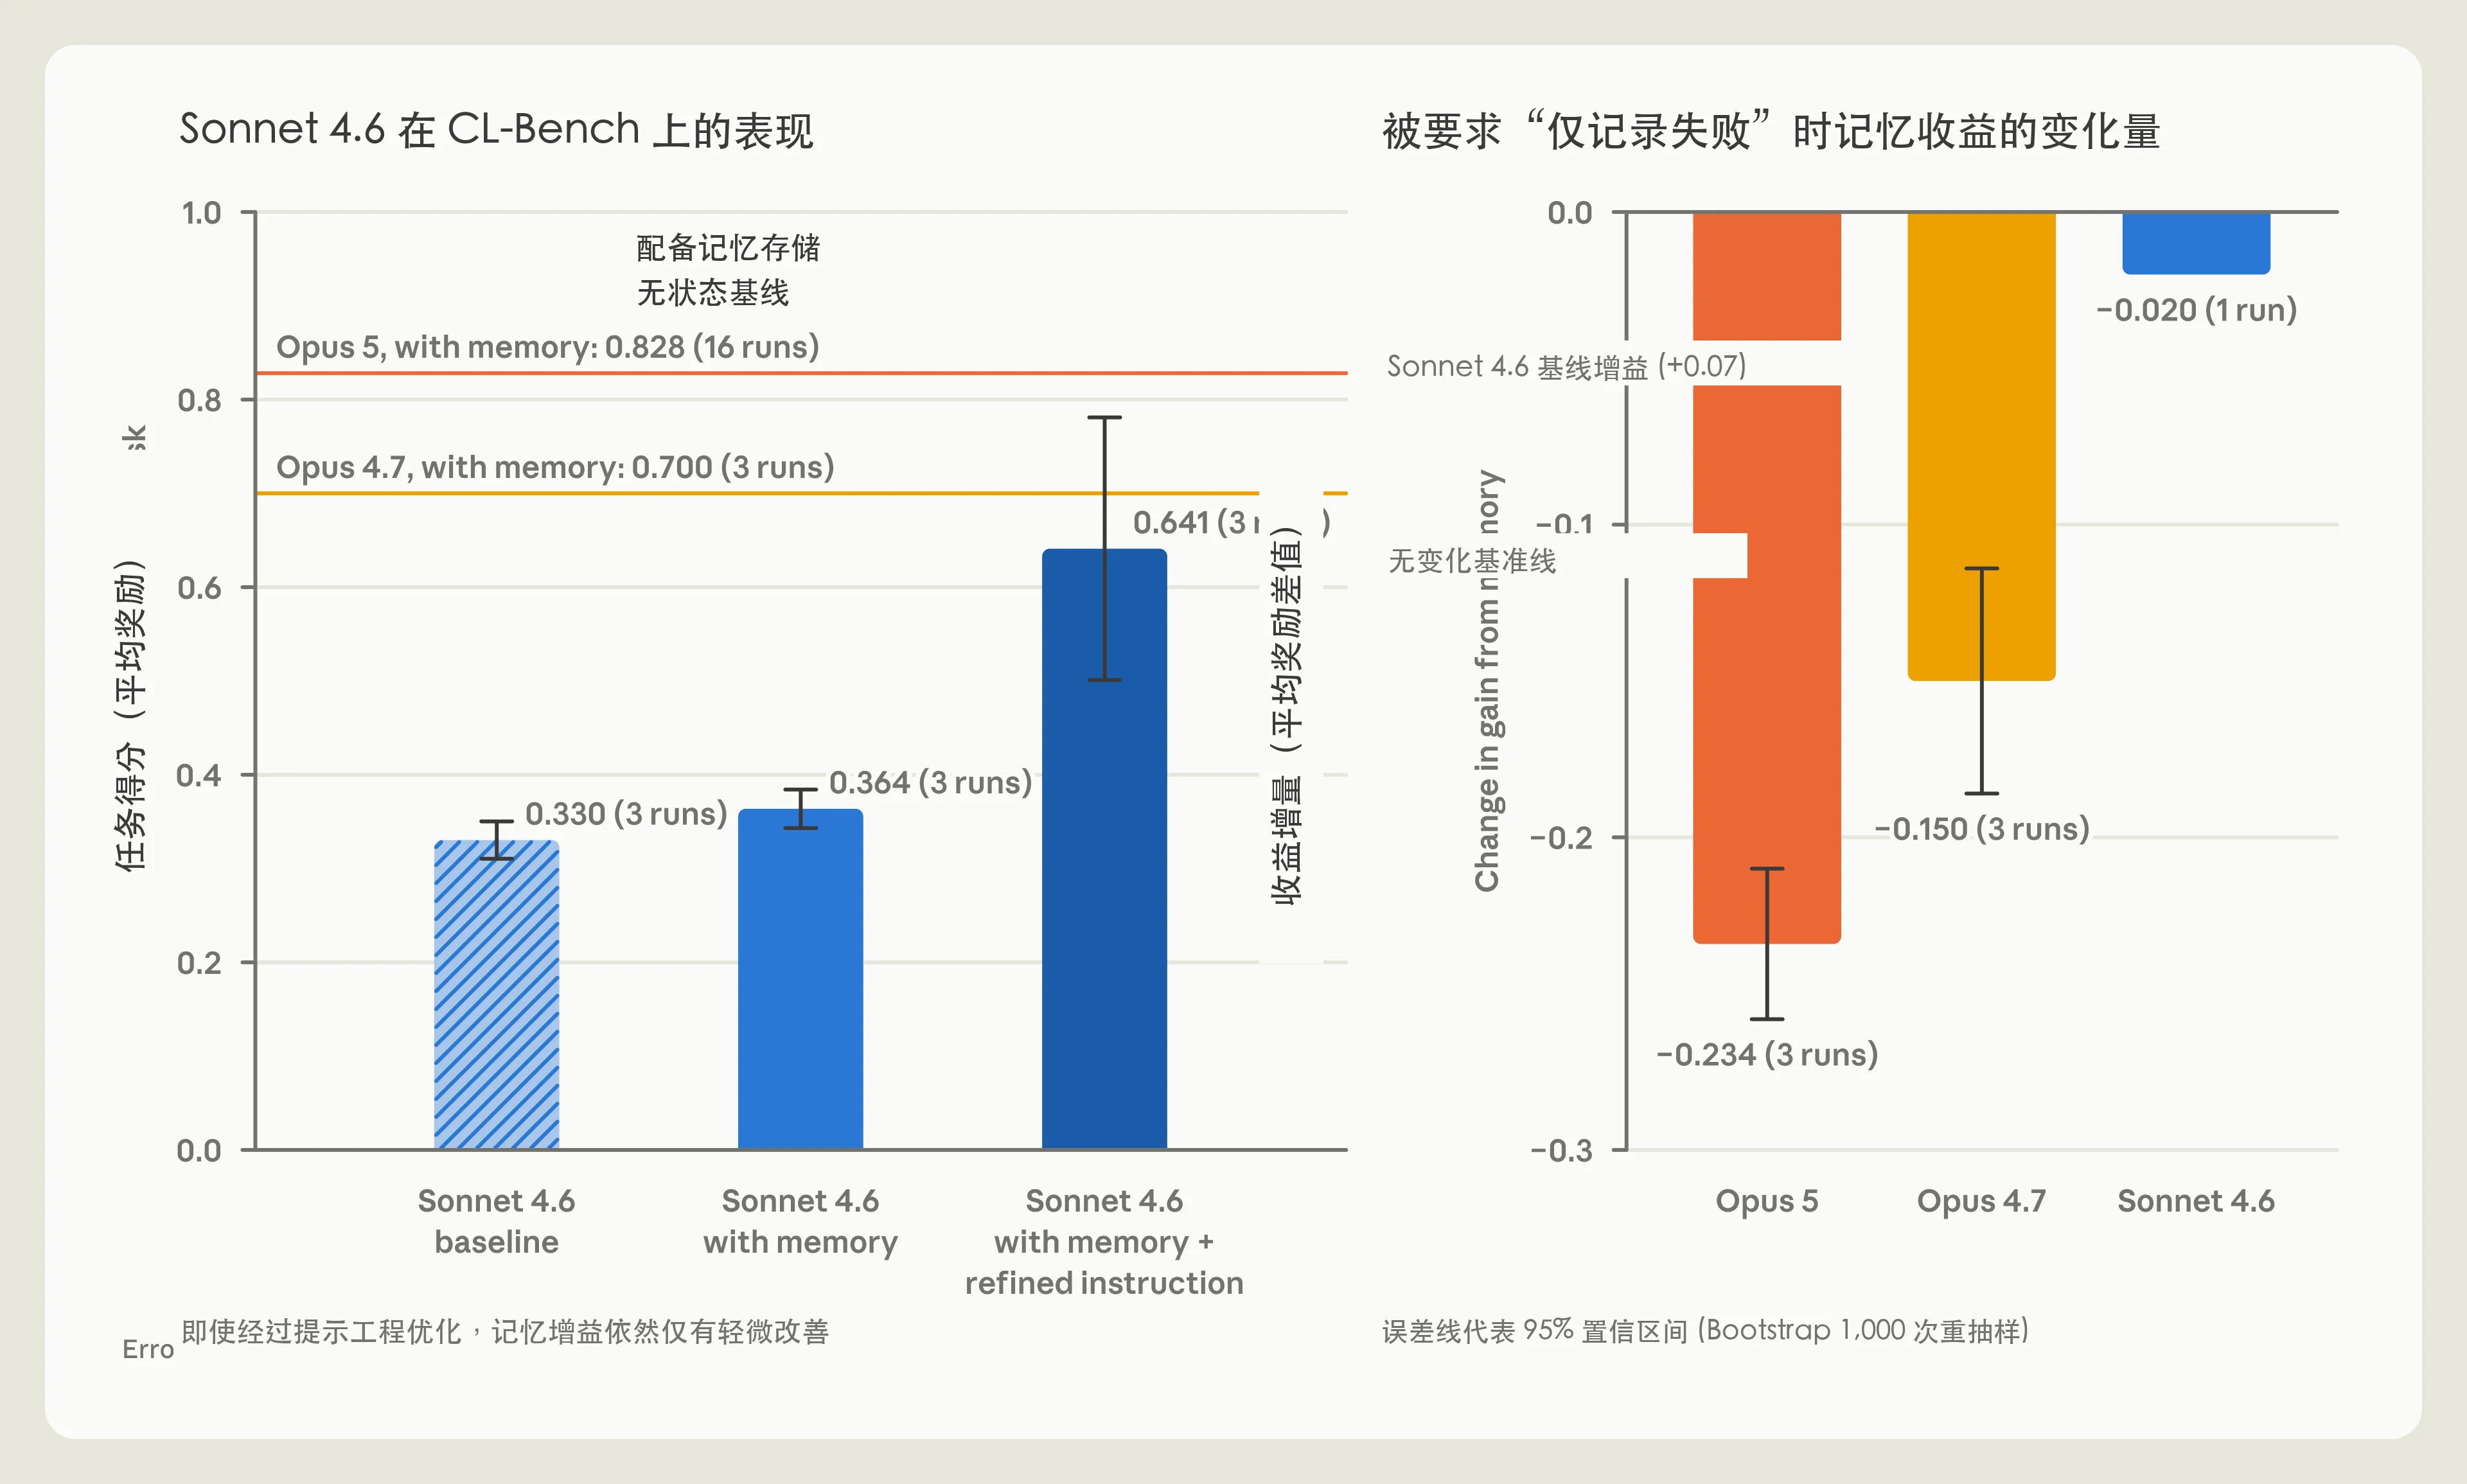
图 5:左图:Sonnet 4.6 在 CL-Bench 数据库任务中有无提示词引导记忆的效果。右图:当模型被要求“只记录失败”时,各模型从记忆中获得的增益变化量。
原文: We also noticed that steering helped older models the most. For instance, Sonnet 4.6 often didn’t read files from its memory directory and failed to test its theories about why an answer was wrong.
我们还注意到,外部引导提示词对早期模型帮助最大。例如,Sonnet 4.6 经常不会主动去读取其记忆目录中的文件,也未能检验其关于错误原因的推测。
原文: In this case, prompting Claude to read its memory files before answering—and then to explicitly test its theories—nearly doubled its benchmark score (Figure 5, left). Sonnet 5 does this on its own. Without being prompted to, it read its memory before answering 9 out of 10 times. By comparison, Sonnet 4.6 did this less than half of the time.
在这种情况下,通过提示词引导 Claude 在回答前先读取记忆文件,并显式测试其推测,使其基准得分几乎翻倍(见图 5 左侧)。而 Sonnet 5 已经能够自主完成这一操作——在没有任何提示的情况下,它在 10 次中有 9 次会在回答前主动读取记忆。相比之下,Sonnet 4.6 主动读取记忆的概率不到一半。
原文: With frontier Claude models, we typically give simple guidance to create memory notes when a person asks them to or when something is clearly worth remembering, and we leave that judgment up to Claude.
对于前沿的 Claude 模型,我们通常只给出简单的原则性指引:在用户要求时或某些内容明确值得记住时创建记忆笔记,并将具体的价值判断全权留给 Claude 自行裁量。
离线做梦可以修正记忆错误 (Dreaming can correct memory)
原文: Since Claude writes to memory based on what it judges to be salient in-session, a note that’s wrong from the start or that drifts as the environment changes can be read, and trusted, by Claude in a later session.
由于 Claude 是基于会话进行时的即时显著性判断来写入记忆的,一条最初就记录错误或因环境改变而失效的笔记,很可能会在后续会话中被 Claude 误读并采信。
原文: Dreaming gives Claude a way to test its notes against the original transcripts (Figure 6). We saw a positive example of this when Claude played Pokémon using Managed Agents with a mounted directory for its memories.
“做梦”(离线整合)为 Claude 提供了一种对照原始会话记录(transcripts)验证其记忆笔记的机制(见图 6)。在 Claude 使用 Managed Agents 挂载持久记忆目录玩《宝可梦》时,我们观察到了一个极佳的正面案例。
原文: Dreaming can correct mistakes in memory.
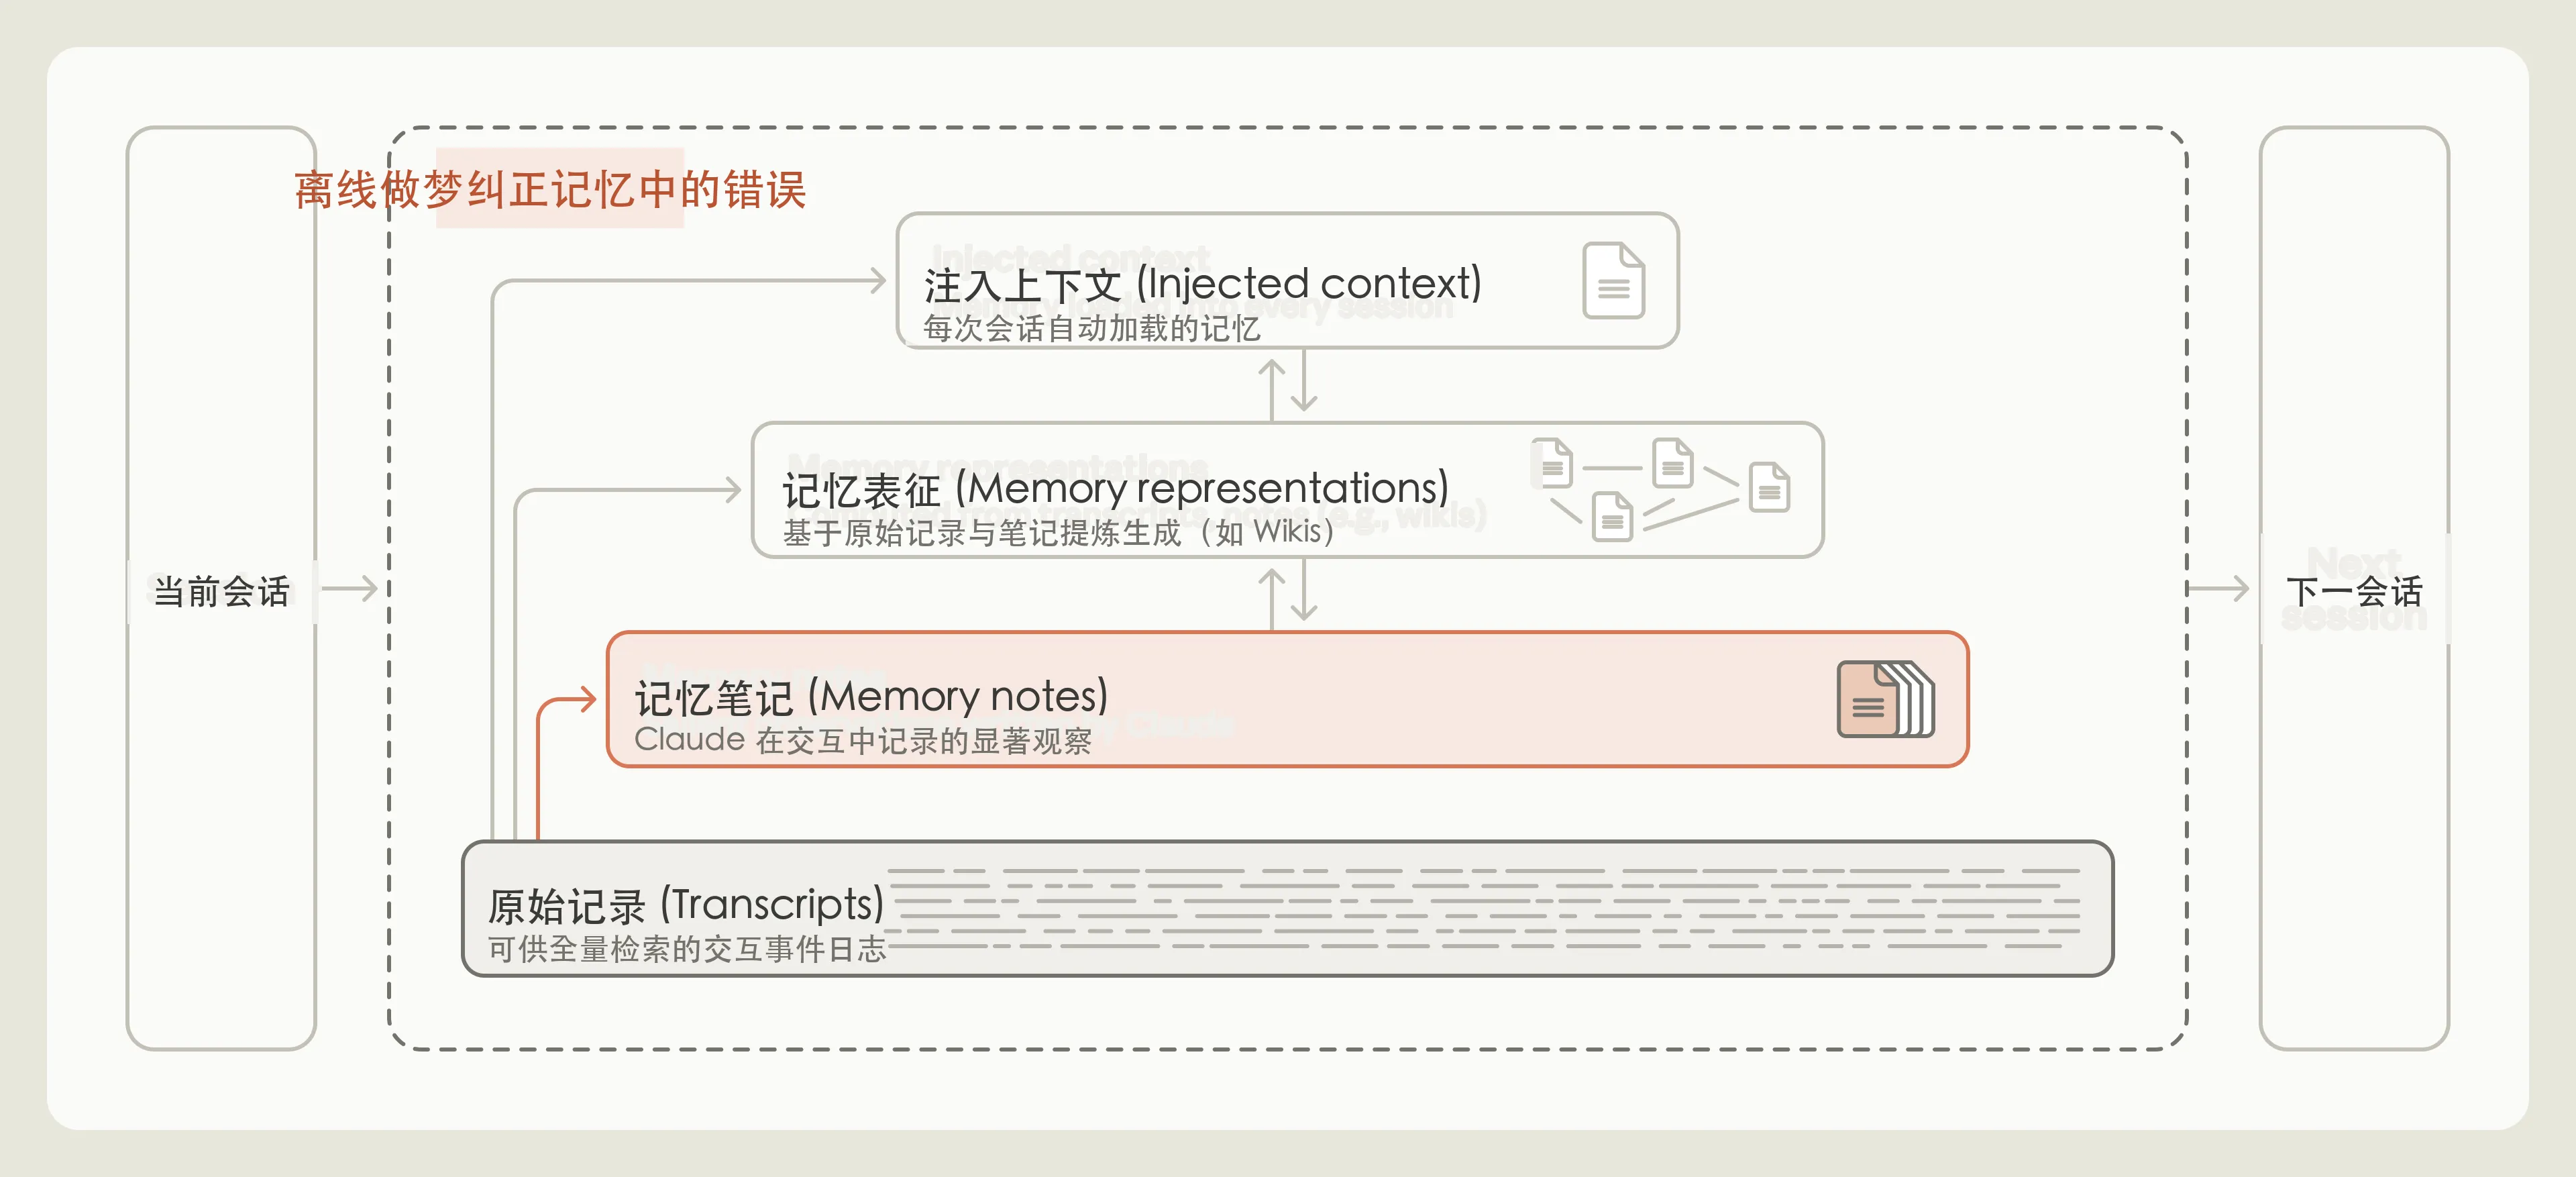
图 6:“做梦”可以纠正记忆中的错误。
原文: In one part of the game, the player has to get through Mt. Moon, a cave system with its entrance on the west side of the map and its exit on the east. Near the entrance is a trap: a one-way ledge that drops the player onto the route they came from, with no clear way to climb back up. Claude was using the PokéCenter, a building at the mountain’s entrance, as a landmark, so whether it walked off the ledge depended on which side of the mountain it thought the PokéCenter was on.
在游戏的某一部分,玩家必须穿过月见山(Mt. Moon)——这是一个西侧为入口、东侧为出口的洞穴系统。在入口附近存在一个地形陷阱:一段单向通行的台阶断崖(ledge),如果跳下就会掉回之前走过的旧路线,且无法直接原路爬回。Claude 当时将坐落在洞穴入口处的宝可梦中心(PokéCenter)作为地标,因此它是否会误跳断崖,完全取决于它认为宝可梦中心处于山体的哪一侧。
原文: At one point, Claude wrote down (incorrectly) that the PokéCenter was on the east side. When it walked out of the PokéCenter, it announced, “Mt Moon is behind me,” and updated its notes: “Mt Moon DONE.” But Mt. Moon was not behind it. A few actions later, Claude went over the ledge and landed back on the route it had come from (Figure 7). Its navigation tool didn’t show the drop, so Claude concluded, “I overshot far west,” and that it had been on the correct side all along. It hadn’t.
在某个时刻,Claude 错误地记录道:宝可梦中心在东侧。当它走出宝可梦中心时,它宣布:“月见山已被抛在身后”,并更新了笔记:“月见山 完成”。但事实上月见山根本没有通过。几步操作之后,Claude 纵身跃下断崖,掉回了它刚来时的路线上(见图 7)。由于它的导航工具没有标注这种单向高低落差,Claude 得出结论:“我向西走过头了”,并坚信自己原本一直在正确的东侧——而事实并非如此。
原文: A corrected memory note changed the outcome in Pokémon. With the uncorrected note, Claude says, “Mt Moon is behind me,” heads for the next city, and ends up back on the route it came from. With the note corrected by dreaming, it says, “Now I need to find the Mt Moon cave entrance to re-enter,” and goes back into the cave.
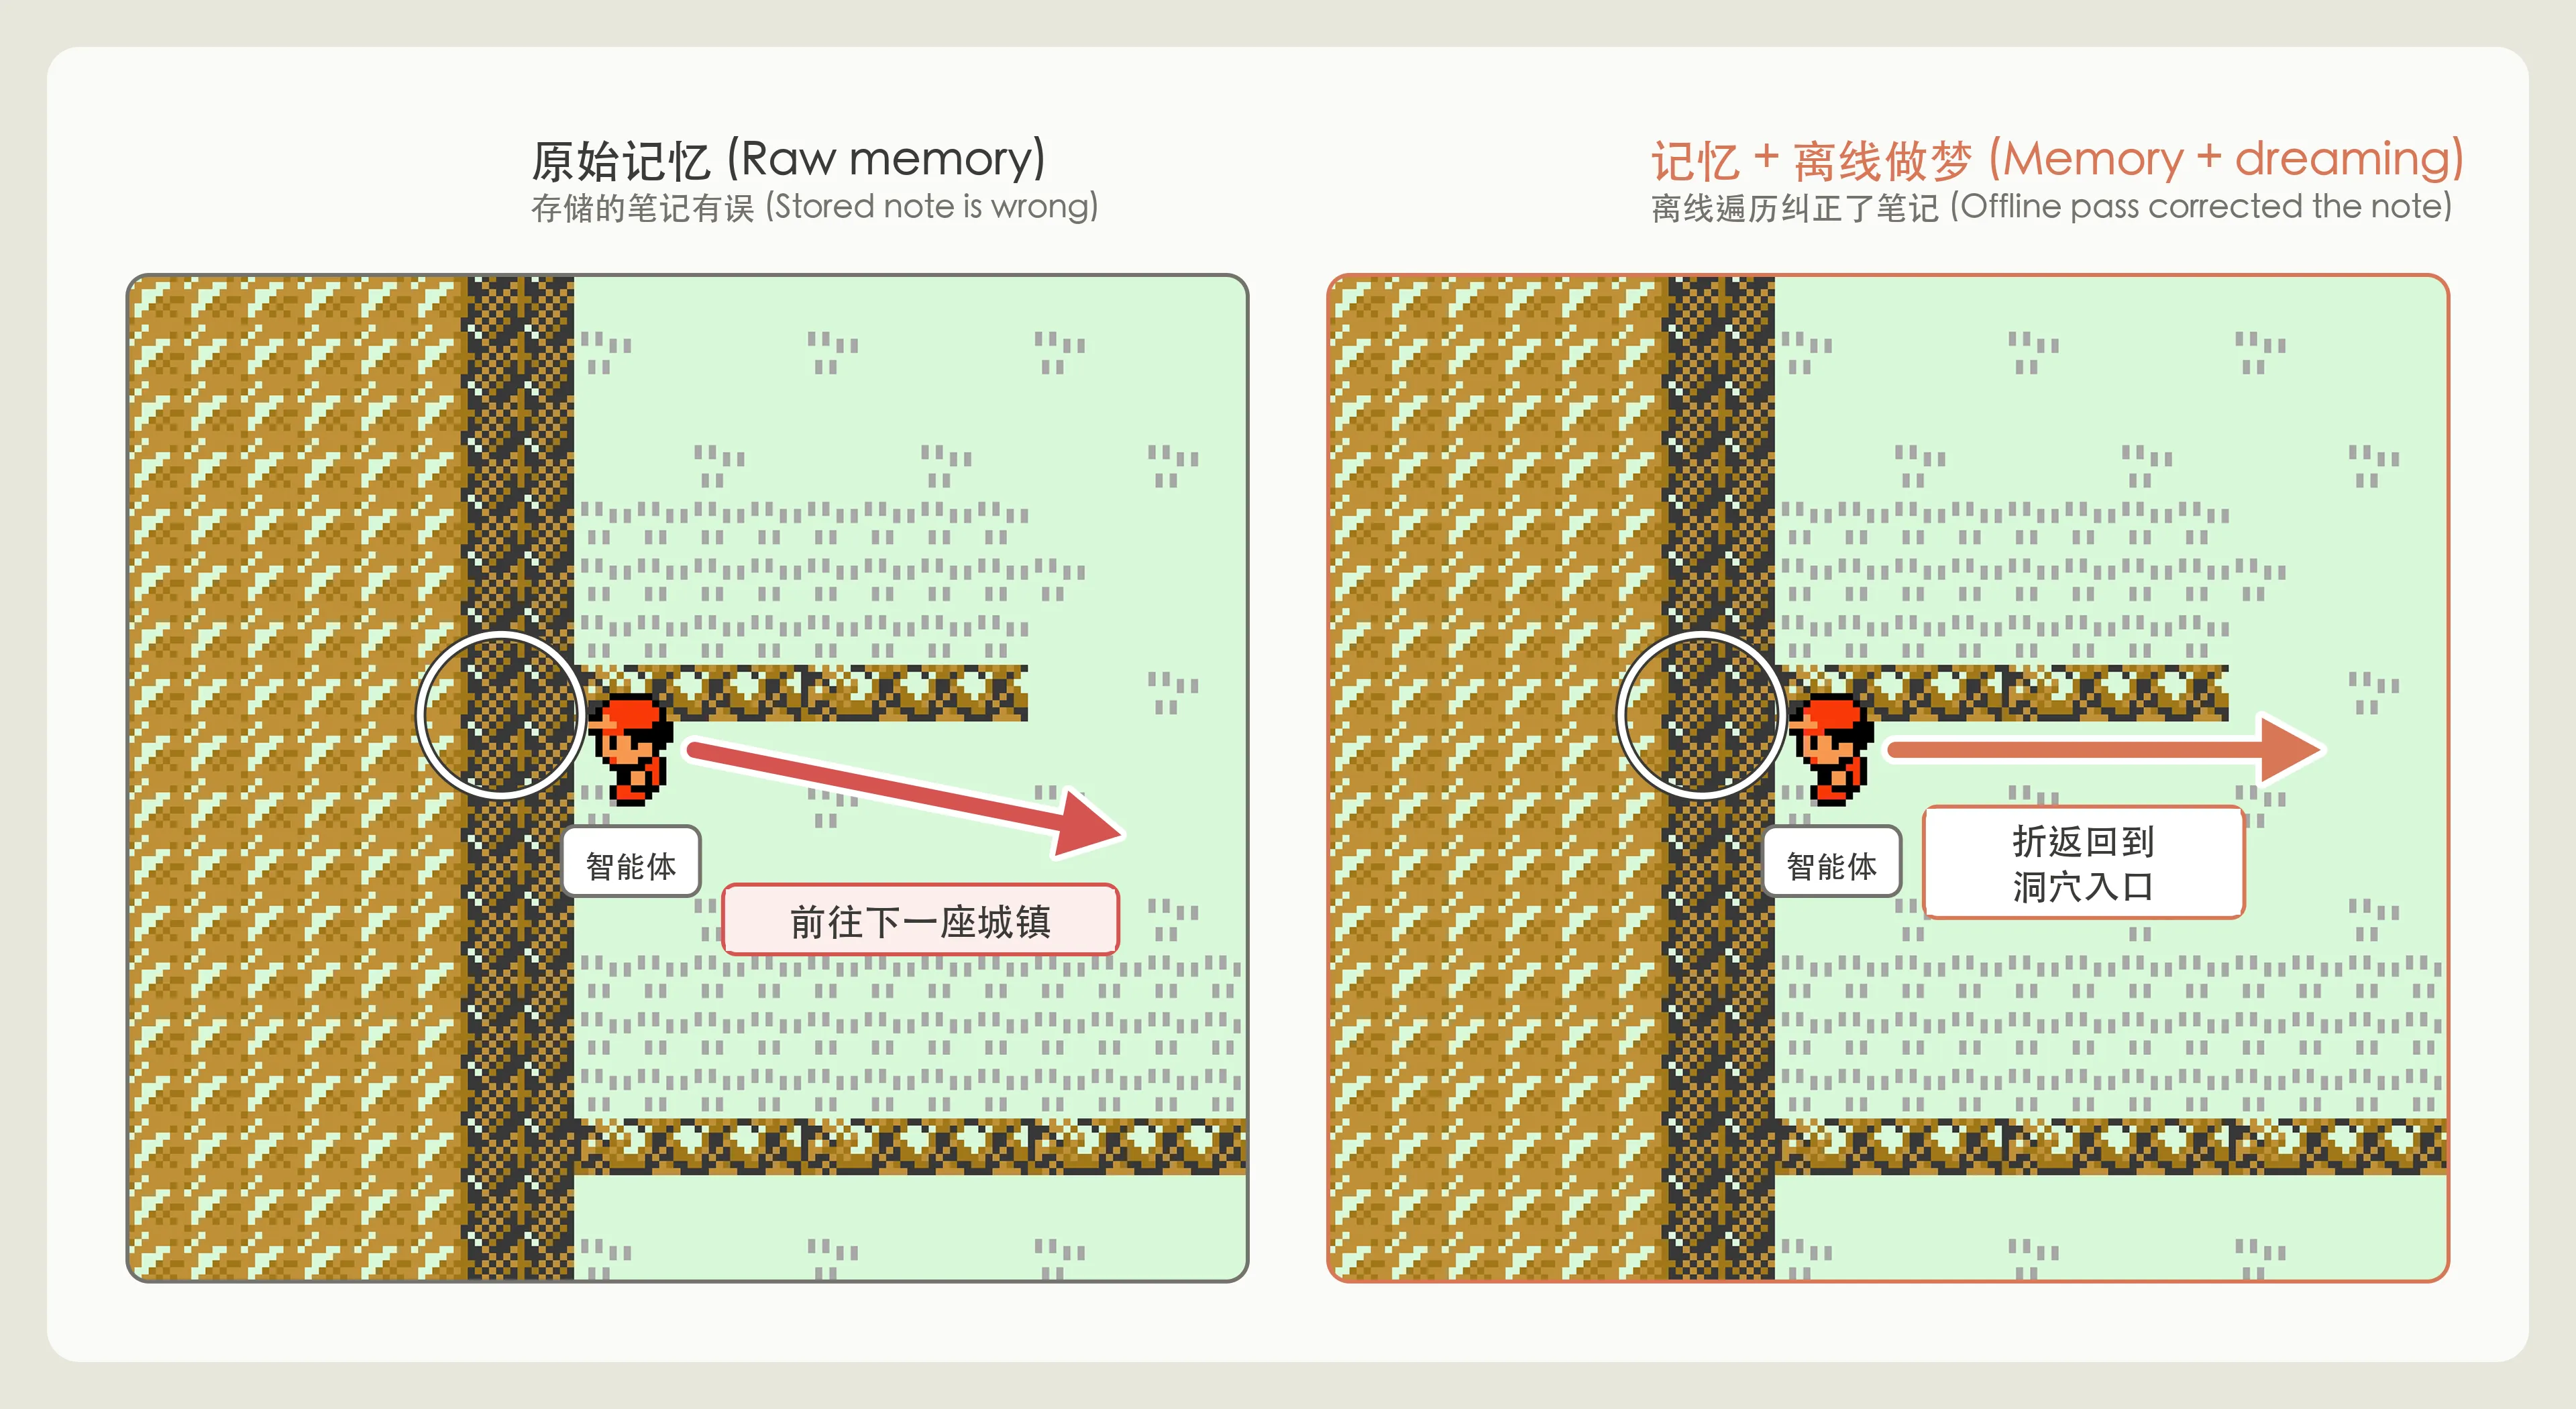
图 7:一条修正后的记忆笔记改变了《宝可梦》游戏中的行动走向。使用未修正的笔记时,Claude 认为“月见山已被甩在身后”,朝着下一座城市前进,最终倒退跌回原本的路线;而在经过“做梦”修正笔记后,它判断“现在需要找到月见山洞口重新进入”,成功折返回洞穴。
原文: We then tested whether dreaming could help Claude avoid this trap. We ran dreaming on the memory folder that contained the wrong location for the PokéCenter: Claude checked the note against the session transcript, caught its error, and rewrote it. The transcript gave Claude a ground truth to validate its memory against. With the corrected memory note, Claude went straight back into Mt. Moon and eventually reached Cerulean City.
随后我们测试了“做梦”能否帮助 Claude 避开这个陷阱。我们在包含错误宝可梦中心位置的记忆文件夹上运行了离线整合:Claude 对照会话历史记录核查了该笔记,发现了自己的逻辑错误并进行了重写。历史记录为 Claude 提供了检验记忆真实性的基准事实(ground truth)。凭借修正后的记忆笔记,Claude 径直重返月见山洞穴,并最终抵达了华蓝市(Cerulean City)。
原文: In the run with the uncorrected note, Claude dropped back onto that earlier route three times. After the third failure, Claude seemed to give up, writing, “I’m going to stop rather than keep looping.” Our setup’s automatic reply instructed it to continue. So it did, all the way back to Pewter City, the town before the mountain, where it hoped to heal and restock. The run ended without Claude ever reaching Cerulean City.
而在未修正笔记的对照组测试中,Claude 连续 3 次跌落回原路。在第 3 次失败后,Claude 似乎放弃了,写道:“我要停下来,不再继续死循环了”。测试框架的自动回复命令它继续推进,于是它一路退回了进山之前的深灰市(Pewter City),希望在那里回血和补给物资。最终这次测试直到结束,Claude 都没能到达华蓝市。
原文: Dreaming corrects the memory, and Claude goes back into the cave and reaches the next city. The run with the uncorrected note (“Raw memory”) never gets past the mountain, and neither does the run with no memory.
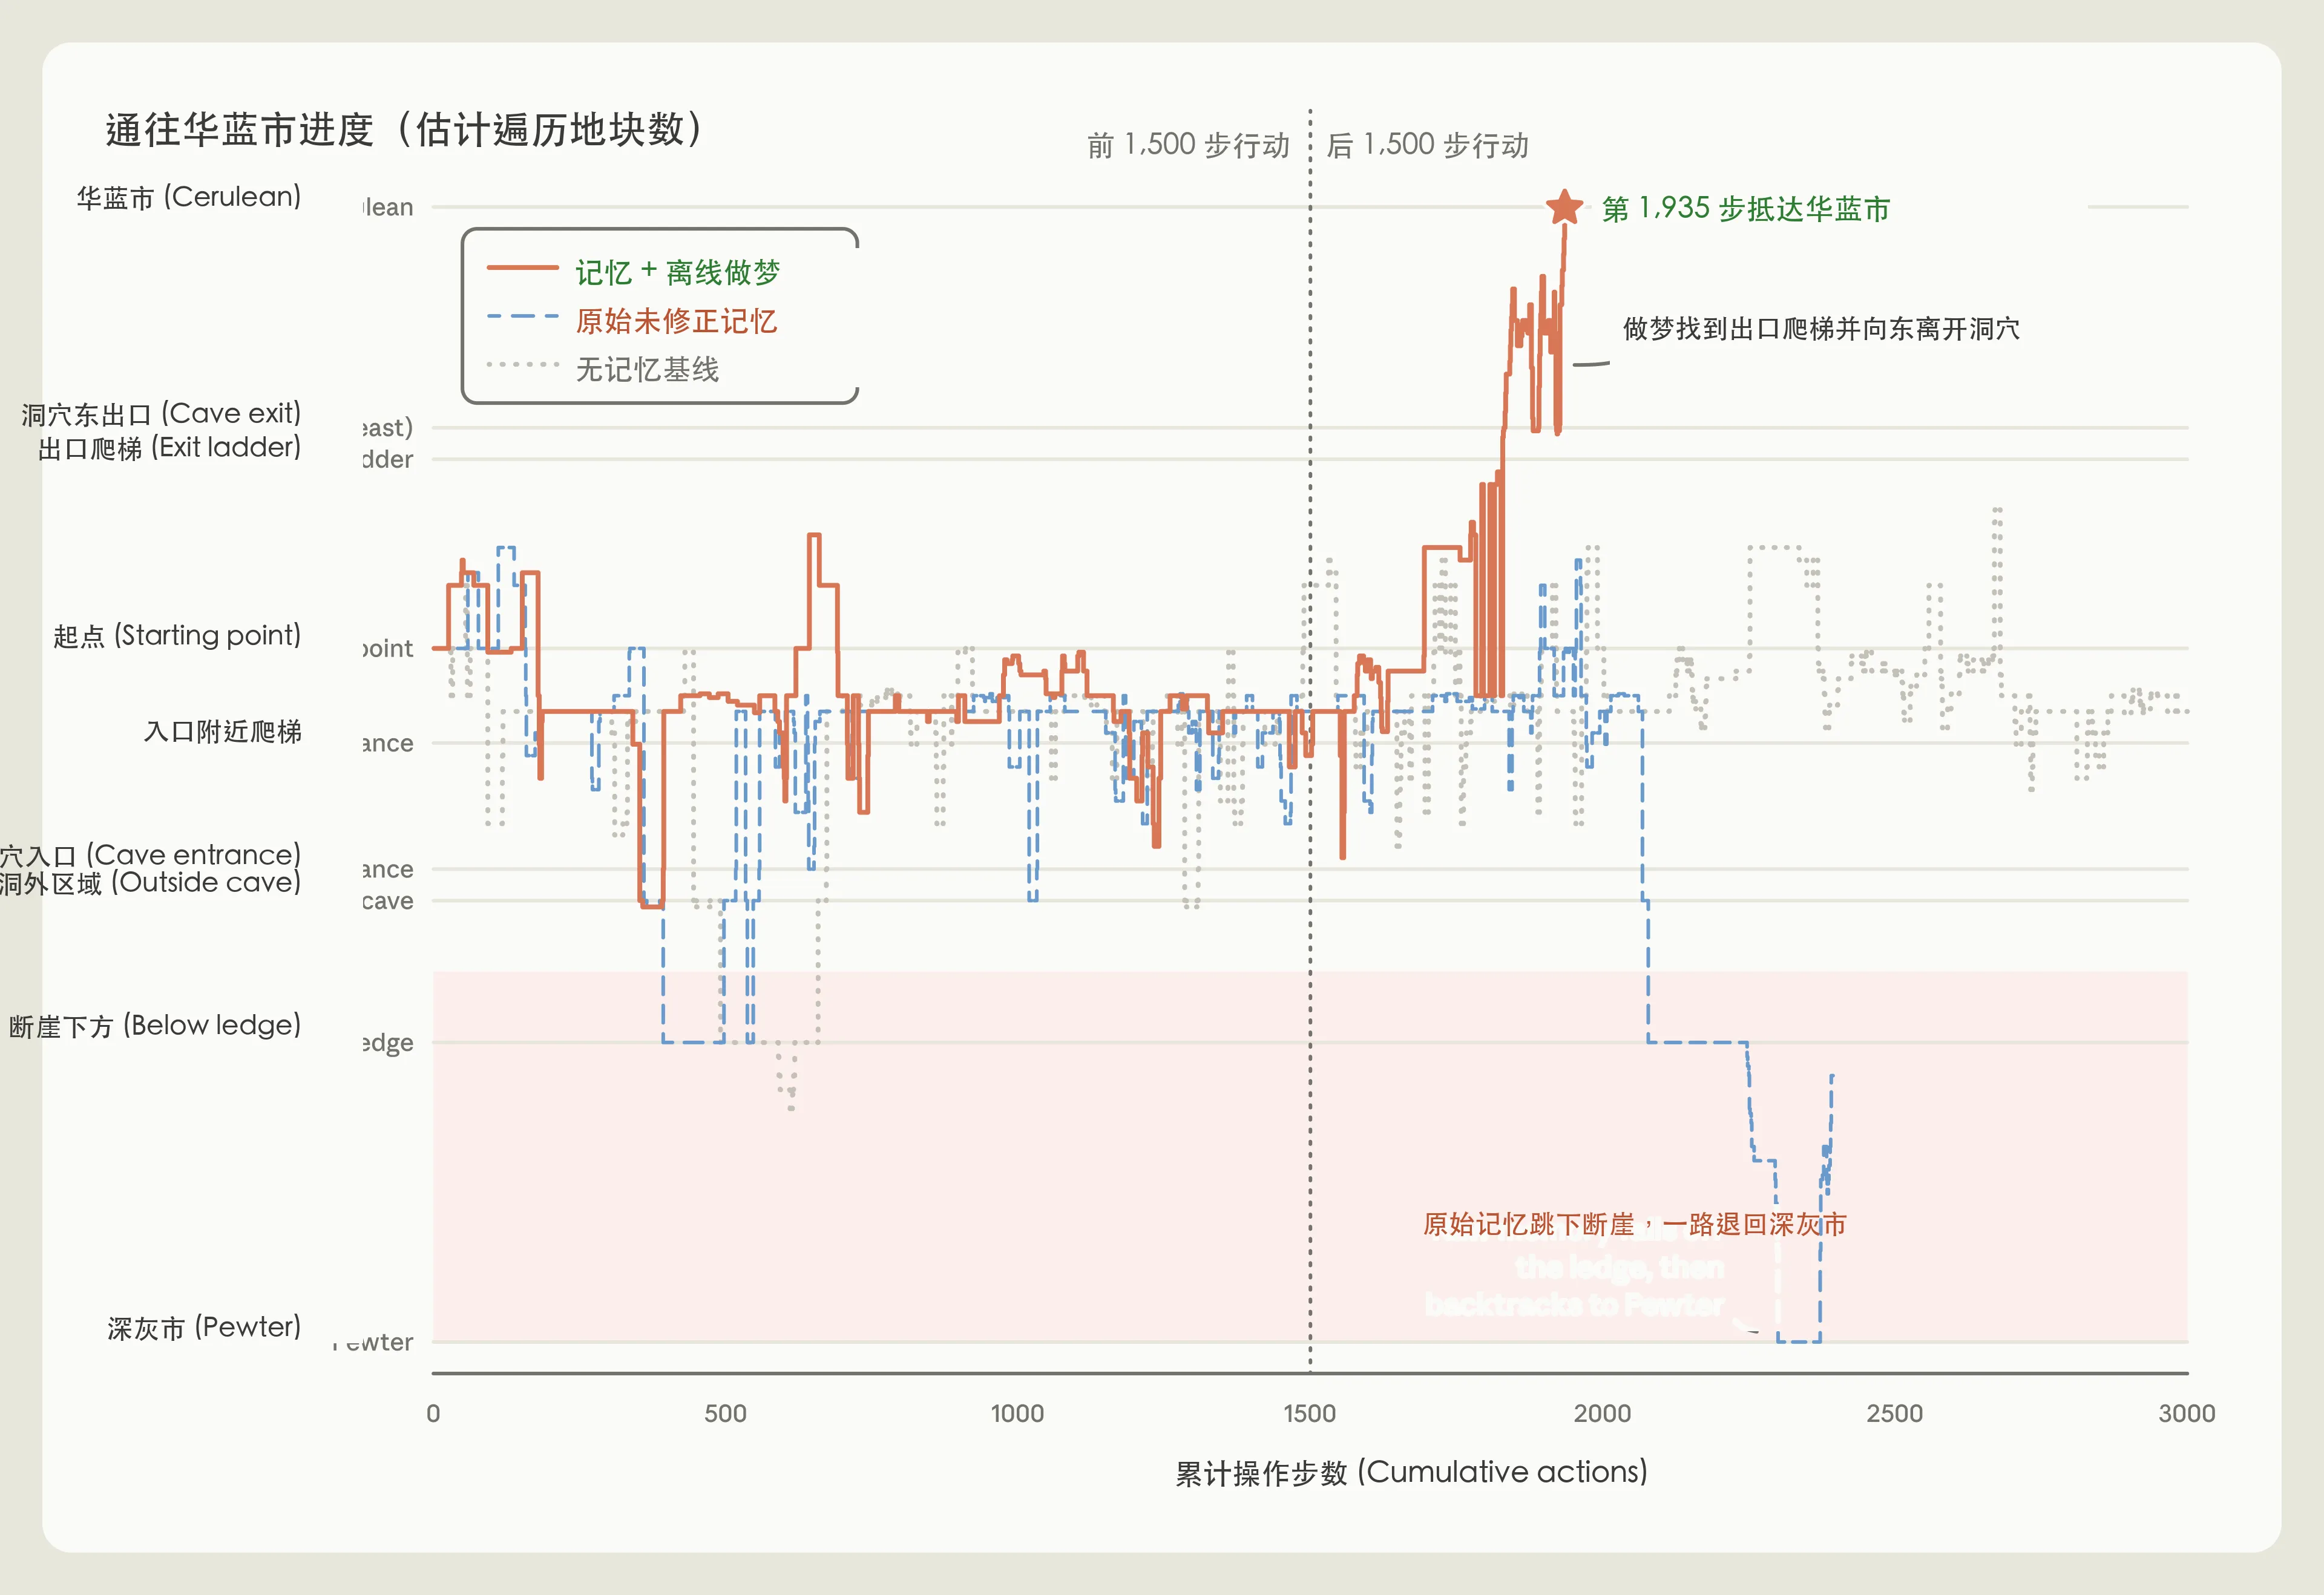
图 8:“做梦”纠正了记忆,Claude 折返回洞穴并成功抵达下一座城市。使用未修正笔记的运行(“原始记忆”)从未越过月见山,无记忆基线的运行同样未能穿过。
离线做梦可以构建全新的知识表征 (Building wiki representations)
原文: With dreaming, Claude can build representations to help navigate memory (Figure 9). One type of memory representation it uses is called a wiki, a collection of pages written and maintained by Claude that gathers what Claude knows about one subject and links it to other notes. These links effectively provide Claude with a map it can use to sift through its memory and efficiently locate memories when they’re needed.
通过离线整合,Claude 能够构建高级知识表征来辅助检索记忆(见图 9)。它所使用的一种核心表征形式被称为 Wiki(维基百科)——这是一套由 Claude 自主编写和维护的页面集合,汇集了 Claude 关于某个主题的认知,并将其与其他笔记相互链接。这些超链接实际上为 Claude 提供了一幅知识地图,使其能够高效穿透记忆网络,并在需要时迅速定位信息。
🟢 译者注:Wiki 知识表征 相当于给智能体建立了一个 Obsidian 式的双向链接个人知识库(PKM)。通过
[[wiki links]]相互引用,智能体将原本扁平的记忆文档升维成了具备图拓扑属性的知识网络,极大降低了长上下文检索的跳步成本。
原文: Dreaming can build memory representations.
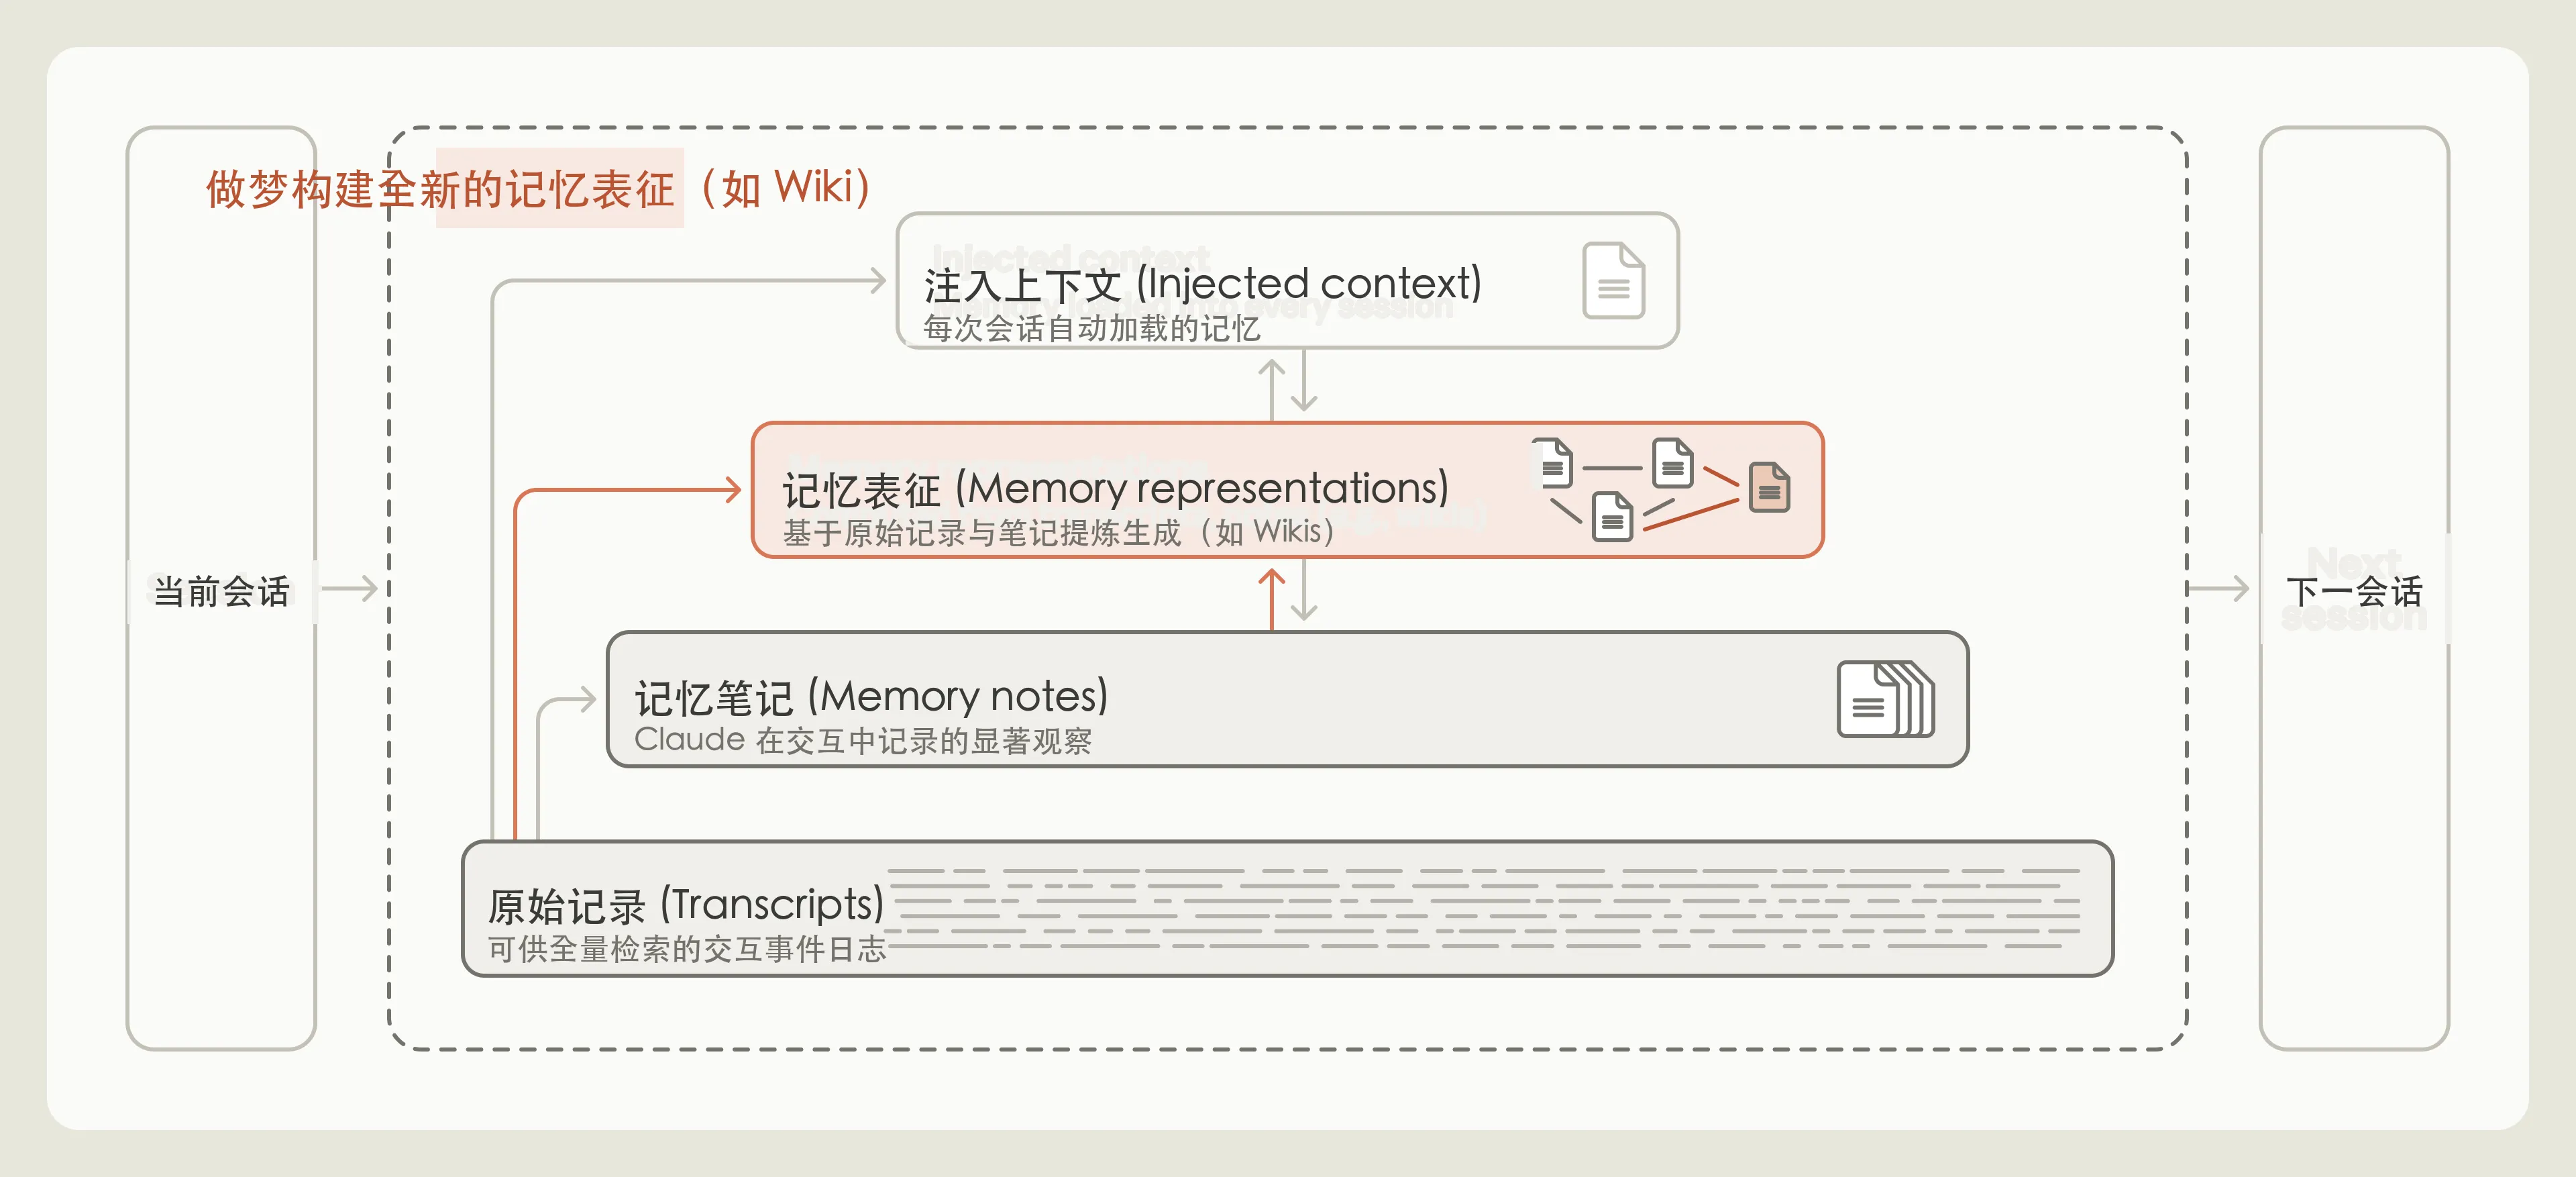
图 9:“做梦”可以构建记忆表征。
原文: Representations like wikis can help Claude traverse its ever-growing knowledge base. We explored the benefit of wikis as a memory representation using a corpus of internal documents—about 350,000 files, roughly 420M tokens—from Stainless, a software company we acquired in May. We created an evaluation set of 25 questions about this corpus and gave Claude a search tool to explore it. We also instructed Claude to build a wiki based on these files using dreaming. Over 128 sessions, we prompted Opus 5 agents to explore the files, write or correct linked wiki pages, merge duplicates, and check claims against the sources.
像 Wiki 这样的结构化表征有助于 Claude 穿梭于不断膨胀的知识库中。我们利用一家名为 Stainless 的软件公司(Anthropic 于 5 月收购)的内部文档语料库(约 35 万个文件,约 4.2 亿 Token)探索了 Wiki 作为记忆表征的价值。我们围绕该语料库设计了包含 25 个复杂问题的评估集,并为 Claude 提供了用于检索文件的 Search 工具。同时,我们指示 Claude 通过离线整合基于这些文件构建一个 Wiki。在 128 个连续会话中,我们提示 Opus 5 智能体探索文档、编写或修正带链接的 Wiki 页面、合并重复内容,并对照原始来源核查断言。
原文: Each session built on the progress that agents made in prior sessions, using a shared log to coordinate work. As we scaled dreaming from two sessions to 128, performance on the 25 questions grew from 13% to 48% of graded criteria (Figure 10).
每个会话都在前序会话的成果上递进,利用共享日志来协调分工。随着我们将离线整合从 2 个会话扩展到 128 个会话,Claude 在 25 个问题上的评测达标率从 13% 跃升到了 48%(见图 10)。
原文: Claude builds its wikis incrementally. After creating an initial wiki, it uses subsequent rounds of dreaming to add to, edit, or prune it. In the early rounds of dreaming, Claude’s knowledge is like that of a new employee, and its ability to answer questions based on the wiki alone is limited. The more it dreams, the richer its knowledge map grows, like that of a seasoned employee. In our tests, we found that the wiki helped Claude the most when we also gave it access to a search tool. When it used both search and the wiki, Claude’s aggregate score rose from 54% to 61% as that wiki grew, compared with 53% when it had access to the search tool alone. Claude’s best score was 48% when it used only the wiki to answer questions. Using search and the wiki also saved about 20,000 tokens per question.
Claude 是以增量方式构建 Wiki 的。在生成初始版本后,它利用随后的离线整合轮次进行补充、编辑或修剪。在早期的整合轮次中,Claude 的知识面类似于刚入职的新员工,仅凭 Wiki 回答问题的能力十分有限。但随着它“做梦”整合的次数增多,其知识地图变得愈发丰富,宛如一位经验老道的老员工。
原文: Center: scores on 25 questions about a corpus of documents from a company as Claude built wikis over sequential sessions. Left and right: an example wiki after two and 128 sessions; each dot is a page, and lines join linked pages.
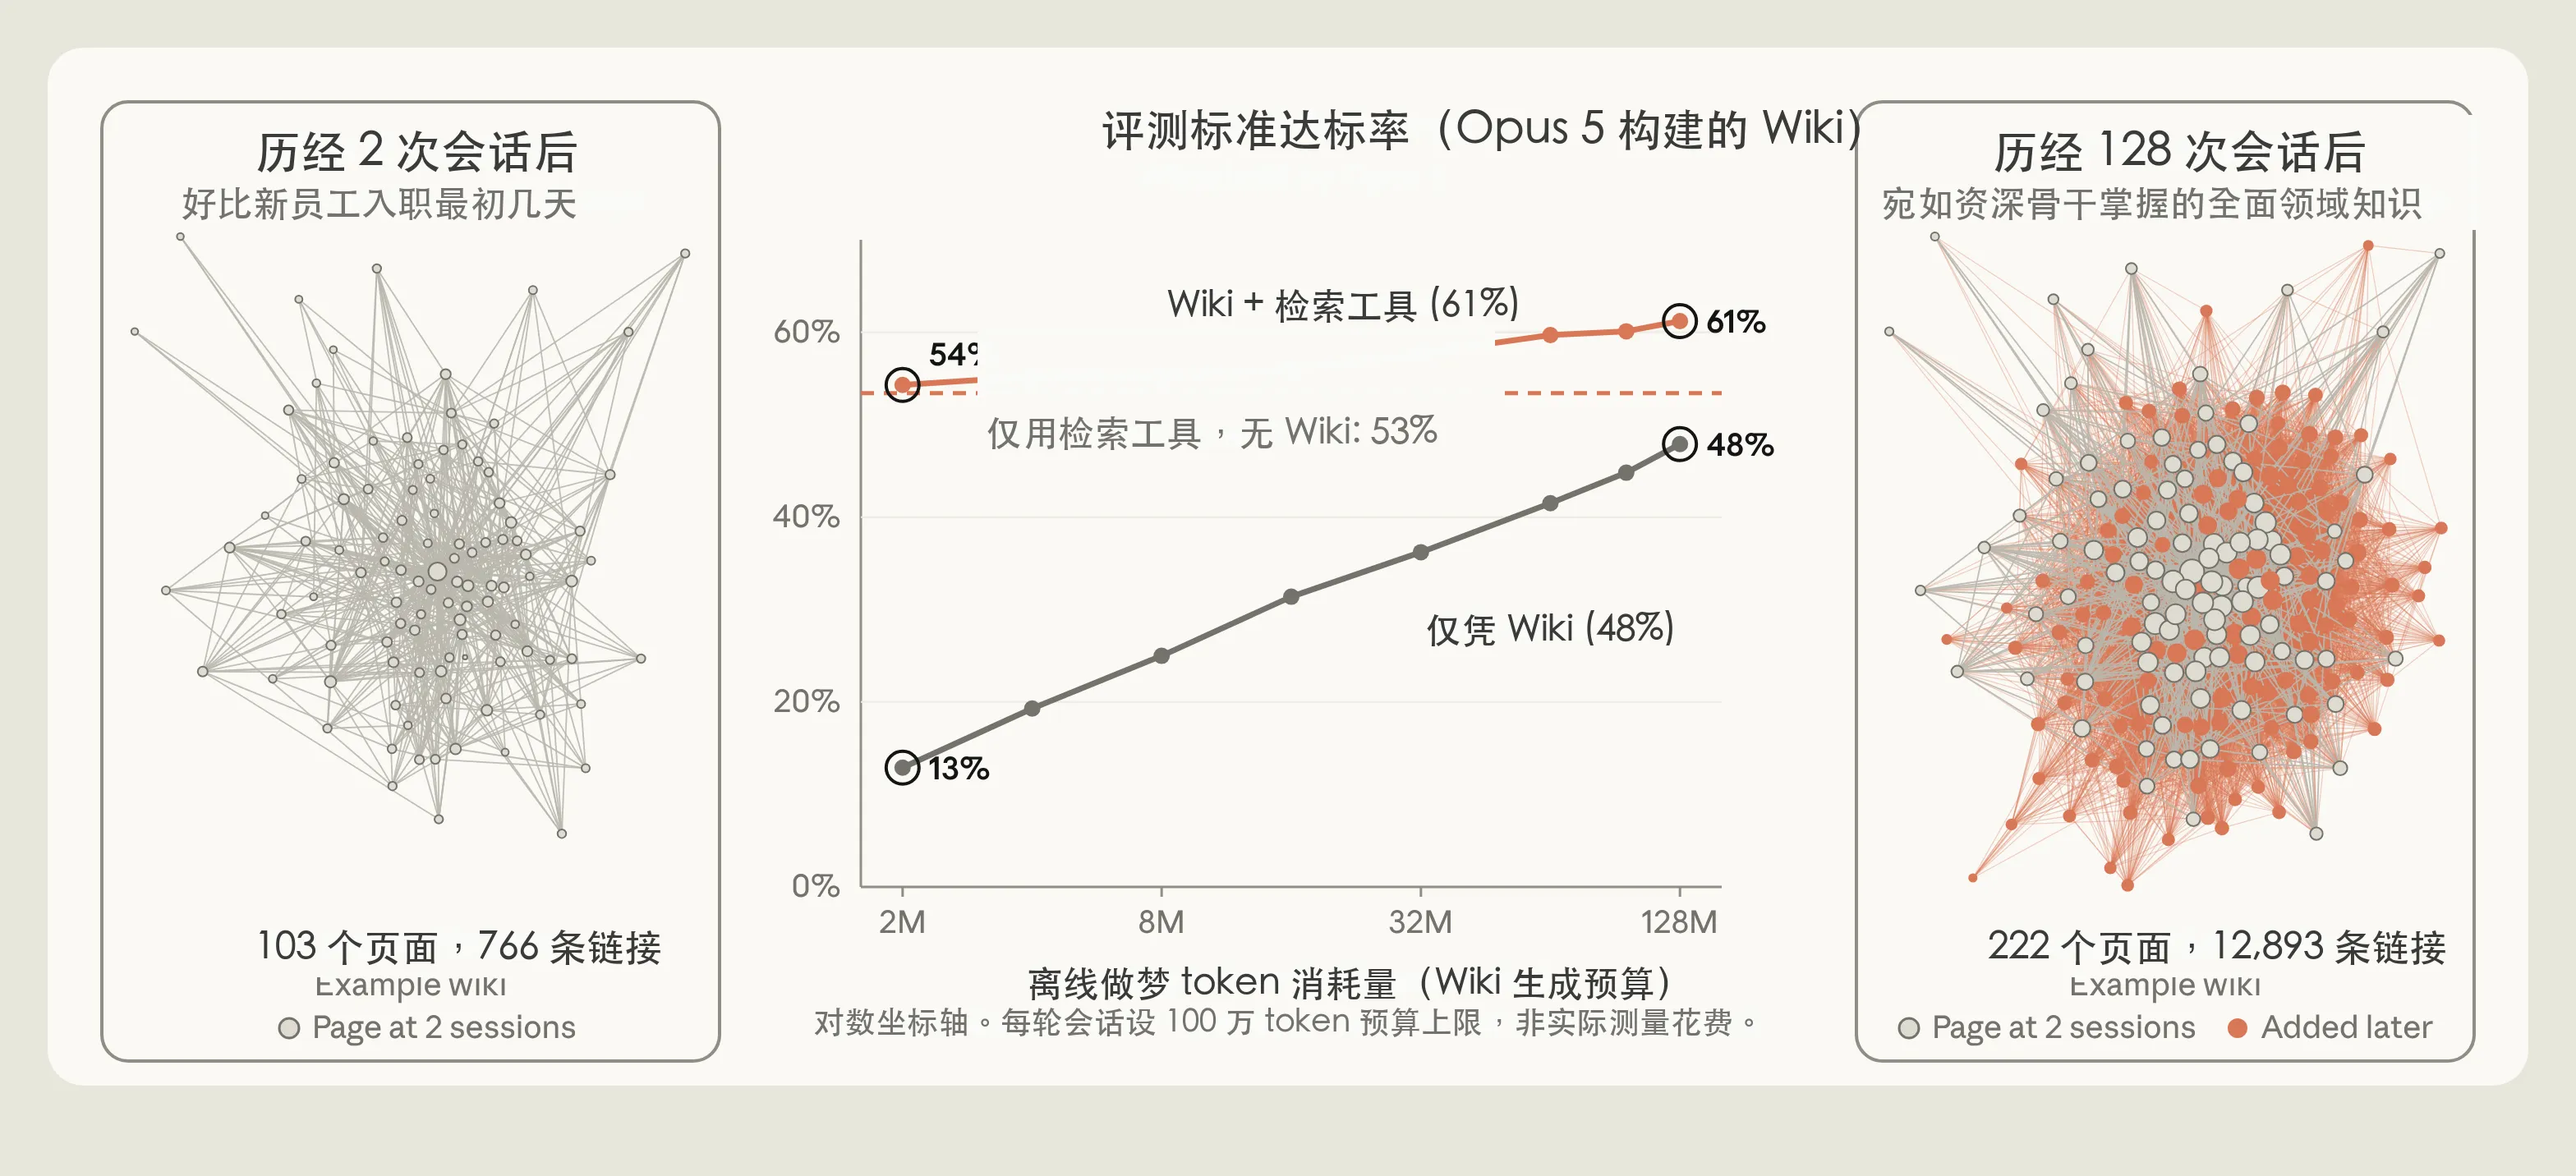
图 10:中间:随着 Claude 在连续会话中逐步构建 Wiki,回答某企业文档语料库 25 个问题的达标得分。左侧和右侧:历经 2 次与 128 次会话后的 Wiki 拓扑示例;每个圆点代表一个页面,连线代表页面间的超链接。
原文: We wanted to test which kinds of tasks benefited from Claude having a wiki. To do this, we used the Harvey LAB benchmark along with a collection of documents about a merger. The benchmark gives Claude a set of documents and asks Claude to generate a legal brief based on their content. The benchmark then grades the brief against a list of criteria. While a tad less engaging, perhaps, than a Pokémon run, these evaluations give us diverse collections of documents to build wikis from.
我们进一步测试了哪些类型的任务能从构建 Wiki 中获益最多。为此,我们使用了 Harvey LAB 基准测试以及一组关于企业并购案的真实法律文档。该基准向 Claude 提供一组案卷,要求 Claude 根据其内容撰写法律摘要,随后根据详细的评分指标清单对摘要进行打分。虽然这种评估可能不如通关宝可梦那么生动,但它们提供了多样化的真实文档集供构建 Wiki。
原文: We instructed Claude to build a wiki from the documents. We then asked Claude to answer questions (about the merger) or generate legal briefs (the LAB benchmark) both from the wiki and from a direct file search. One test asked 24 questions about the merger (Figure 11, left), more than half of which needed Claude to find information across several documents, and many of which also needed Claude to use judgment or do math. On those items (red and orange lines), Claude scored 87% when it consulted the wiki, compared with 73% when it used search alone.
我们让 Claude 从这批文档中生成 Wiki,随后要求 Claude 分别通过 Wiki 与直接文件搜索来回答问题(并购任务)或生成法律摘要(LAB 任务)。其中一项测试针对并购案提出了 24 个问题(见图 11 左侧),其中超过一半的问题需要 Claude 跨多个文档综合提取信息,并且许多问题还需要结合逻辑判断或数学计算。在这些多文档综合条目上(红线与橙线),Claude 在查阅 Wiki 时的得分达到了 87%,而仅使用搜索工具时的得分仅为 73%。
原文: Each panel lists what was graded (left) and the source documents needed to meet each one (right). Left: 24 questions about a merger, which can be answered by looking at mostly public filings. More than half of the criteria required combining information from several documents. Right: a LAB task where the wiki showed no clear gain. Most criteria could be met from a single document.
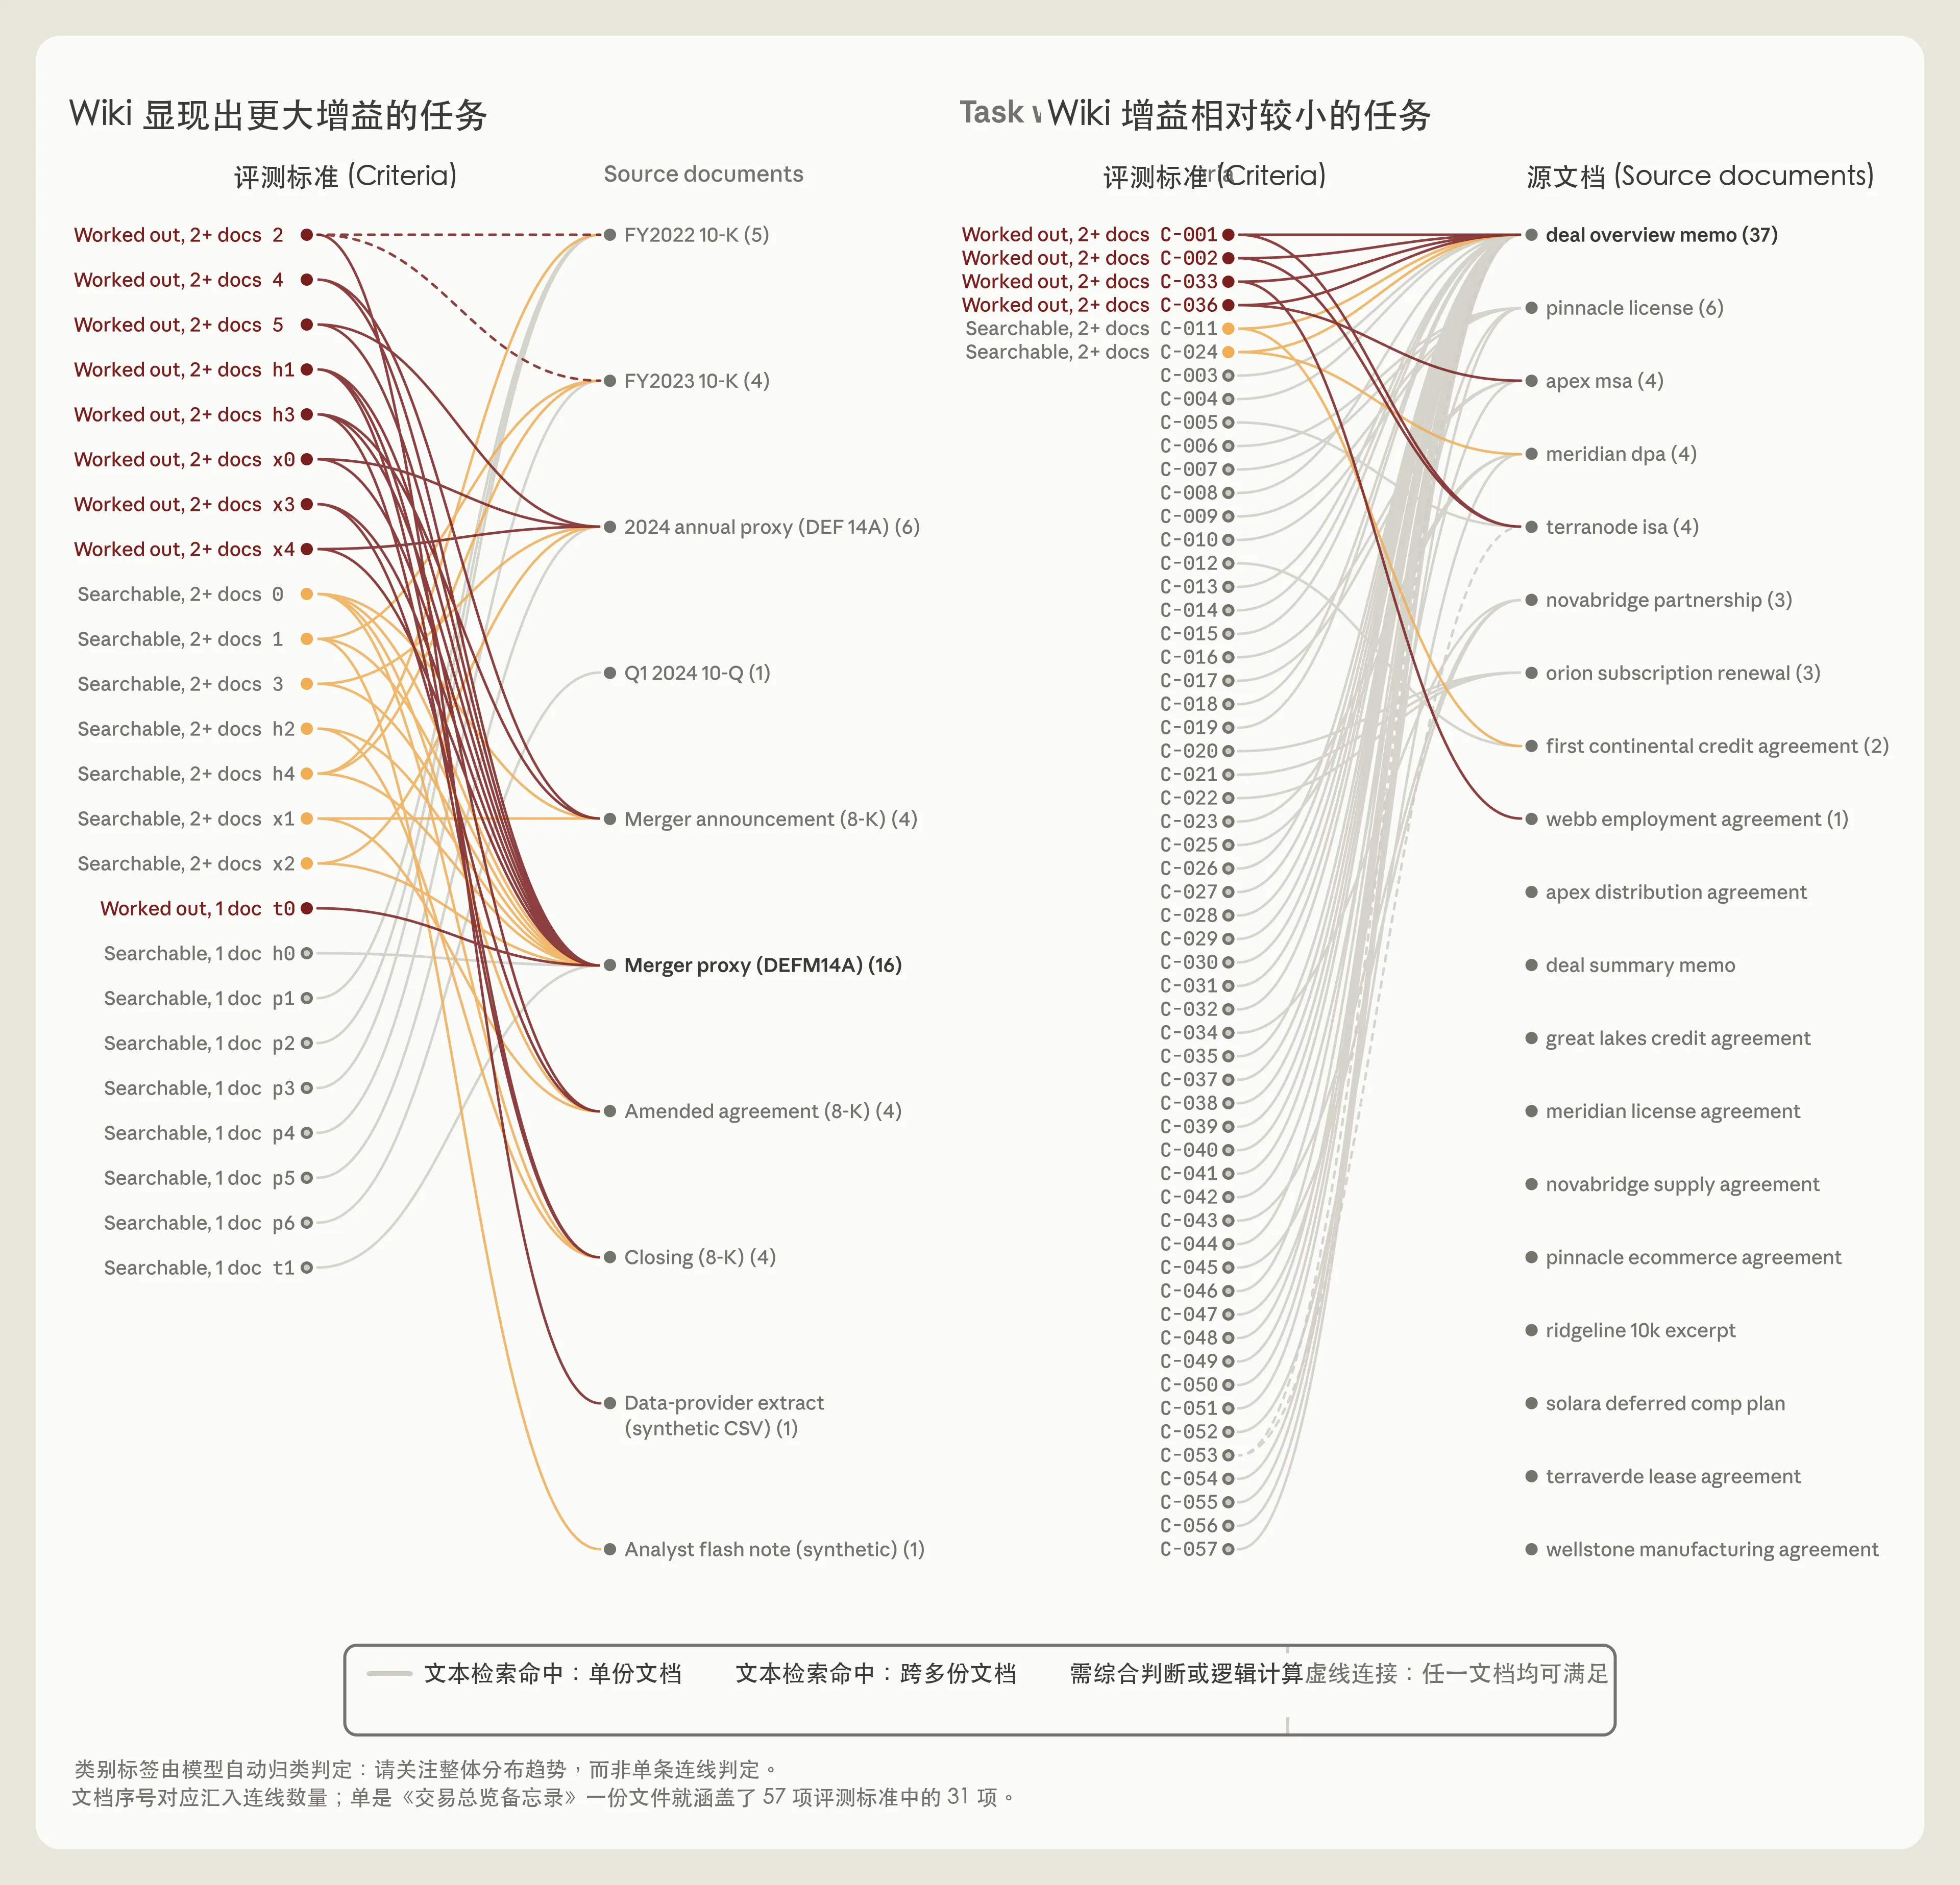
图 11:两幅图表分别列出了评测指标(左侧)与满足该指标所需的源文档(右侧)。左图:关于一项企业并购案的 24 道问题,主要通过公开备案文件解答,其中超半数指标须拼合跨多篇文档的信息。右图:一项 Wiki 未显现出明显增益的 LAB 法律任务,绝大多数指标仅通过检索单篇文档即可满足。
原文: In other cases, the wiki was less useful. On one LAB task (Figure 11, right), brief criteria often could be retrieved with a text search from a single document, and the wiki showed no clear gain in performance relative to search. On another LAB task, the wiki grew larger than the documents themselves (Figure 12). Like the mapmakers in Borges’s one-paragraph short story “On Exactitude in Science,” who drafted a map so detailed it was as large as the empire it represented, Claude had made an extremely detailed wiki that effectively abstracted nothing.
但在其他场景下,Wiki 的价值并不明显。在另一项 LAB 任务中(见图 11 右侧),摘要所需的条件往往可以通过文本检索在单一文档中直接命中,此时 Wiki 相比直接搜索并未展现出明确的性能优势。而在另一项 LAB 任务中,Wiki 的体积甚至膨胀得比原始文档本身还要庞大(见图 12)。正如博尔赫斯在一篇仅一段话的短篇小说《论科学的精确性》中所描绘的制图师那样——他们绘制了一幅精细至极的地图,其尺寸竟与帝国版图一模一样——Claude 制造了一个极度冗余的 Wiki,实际上丧失了任何信息抽象提炼的意义。
原文: The wiki grew to be larger than the raw files.
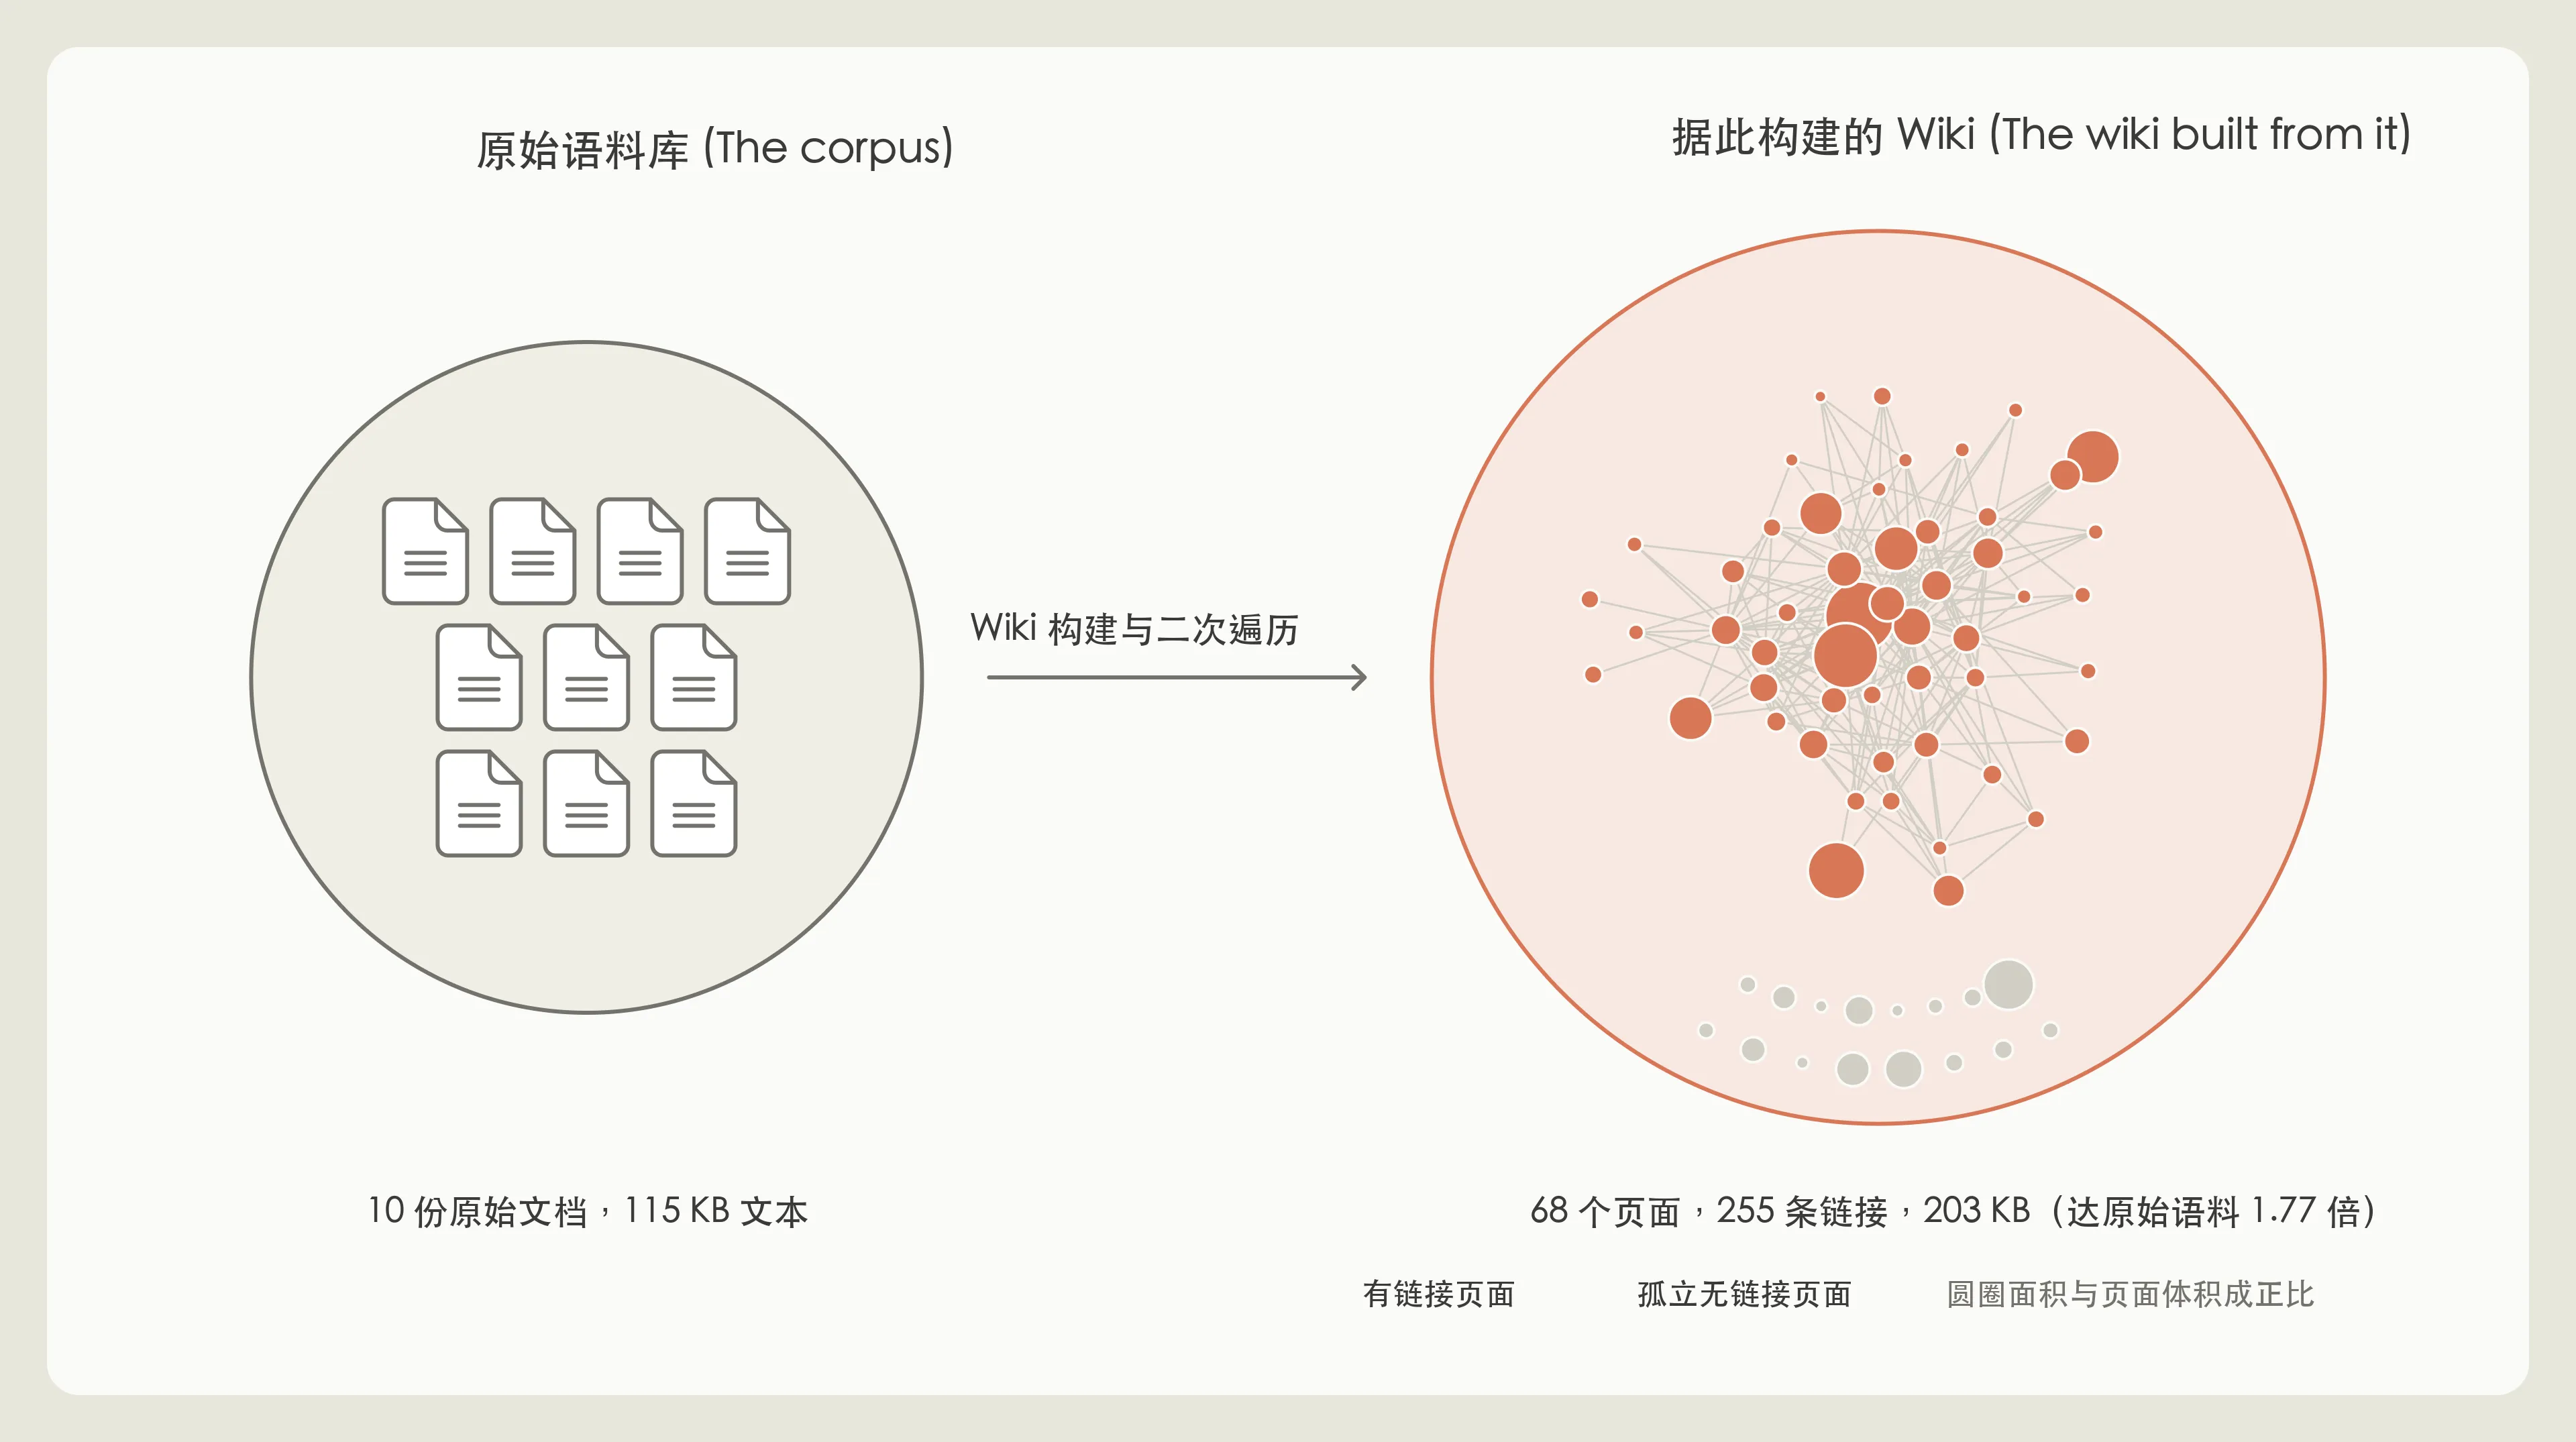
图 12:构建的 Wiki 维基规模膨胀至超过原始文件的 1.77 倍。
离线做梦可以将笔记提升到记忆层级顶端 (Promoting notes up the hierarchy)
原文: Dreaming can also float notes to the top of the memory hierarchy, and the agent harness can preemptively load them into Claude’s context at the start of every session (Figure 13). This means Claude doesn’t need to search for them, or even to know there’s something to search for.
离线整合还可以将关键笔记提升至记忆层级的最顶层,智能体运行时环境(agent harness)可以在每个会话开始时,预先将这些核心上下文加载到 Claude 的上下文窗口中(见图 13)。这意味着 Claude 无需主动发起搜索,甚至在不知道该搜什么的情况下就能直接获知这些背景信息。
原文: Promoting memories into a new session (a form of context injection) must be done carefully. Injected memories use up valuable tokens, and an incorrect note can be carried into every session. Loading a note also doesn’t guarantee that Claude acts on it: our documentation on Claude Code warns that longer instruction files reduce adherence. So the top layer of the memory hierarchy has to stay relatively small, and much of dreaming’s work here is keeping it that way—by moving some details down the hierarchy and leaving links behind.
然而,将记忆注入新会话(即上下文注入 / Context Injection)必须非常克制。注入的记忆会挤占宝贵的上下文窗口 Token,而且一条错误的笔记一旦被顶层注入,就会污染每一个后续会话。同时,预加载笔记并不等同于 Claude 一定会严格执行:我们针对 Claude Code 的文档中就曾警示,指令文件过长会导致模型遵从度下降。因此,记忆层级的顶层必须保持高度精简,而离线整合在这里的一大核心职责正是通过“将非核心细节下沉到下层、并在顶层仅保留索引链接”来维持顶层的极致简洁。
🟢 译者注:上下文注入(Context Injection) 是一柄双刃剑。预先注入能让智能体一启动就带着核心经验,但会侵占宝贵的 Context Window;这也是为什么在 Claude Code 官方架构规范中,注入层被硬性限制为仅读取
MEMORY.md的前 200 行或前 25 KB。
原文: Claude Code’s auto memory keeps its injected layer small in the same way, with Claude maintaining it during the session. Claude doesn’t load all of its auto memory into every session’s context window. It loads only the first 200 lines or 25 KB of MEMORY.md . This header serves as an index, which shows Claude what it knows and where to find it.
Claude Code 的自动记忆(auto memory)功能也以同样的方式保持其注入层的精炼,由 Claude 在会话期间动态维护。Claude 并不会将所有自动记忆全量塞入每次会话的上下文窗口中,而是仅加载 MEMORY.md 的前 200 行或前 25 KB。这部分头部内容起到了索引目录的作用,明确告知 Claude 它已知晓什么,以及去哪里能查到具体详情。
原文: Dreaming can write to the top of the memory hierarchy. Injected context is loaded into every session, and the layers below it are read or searched when Claude needs them.
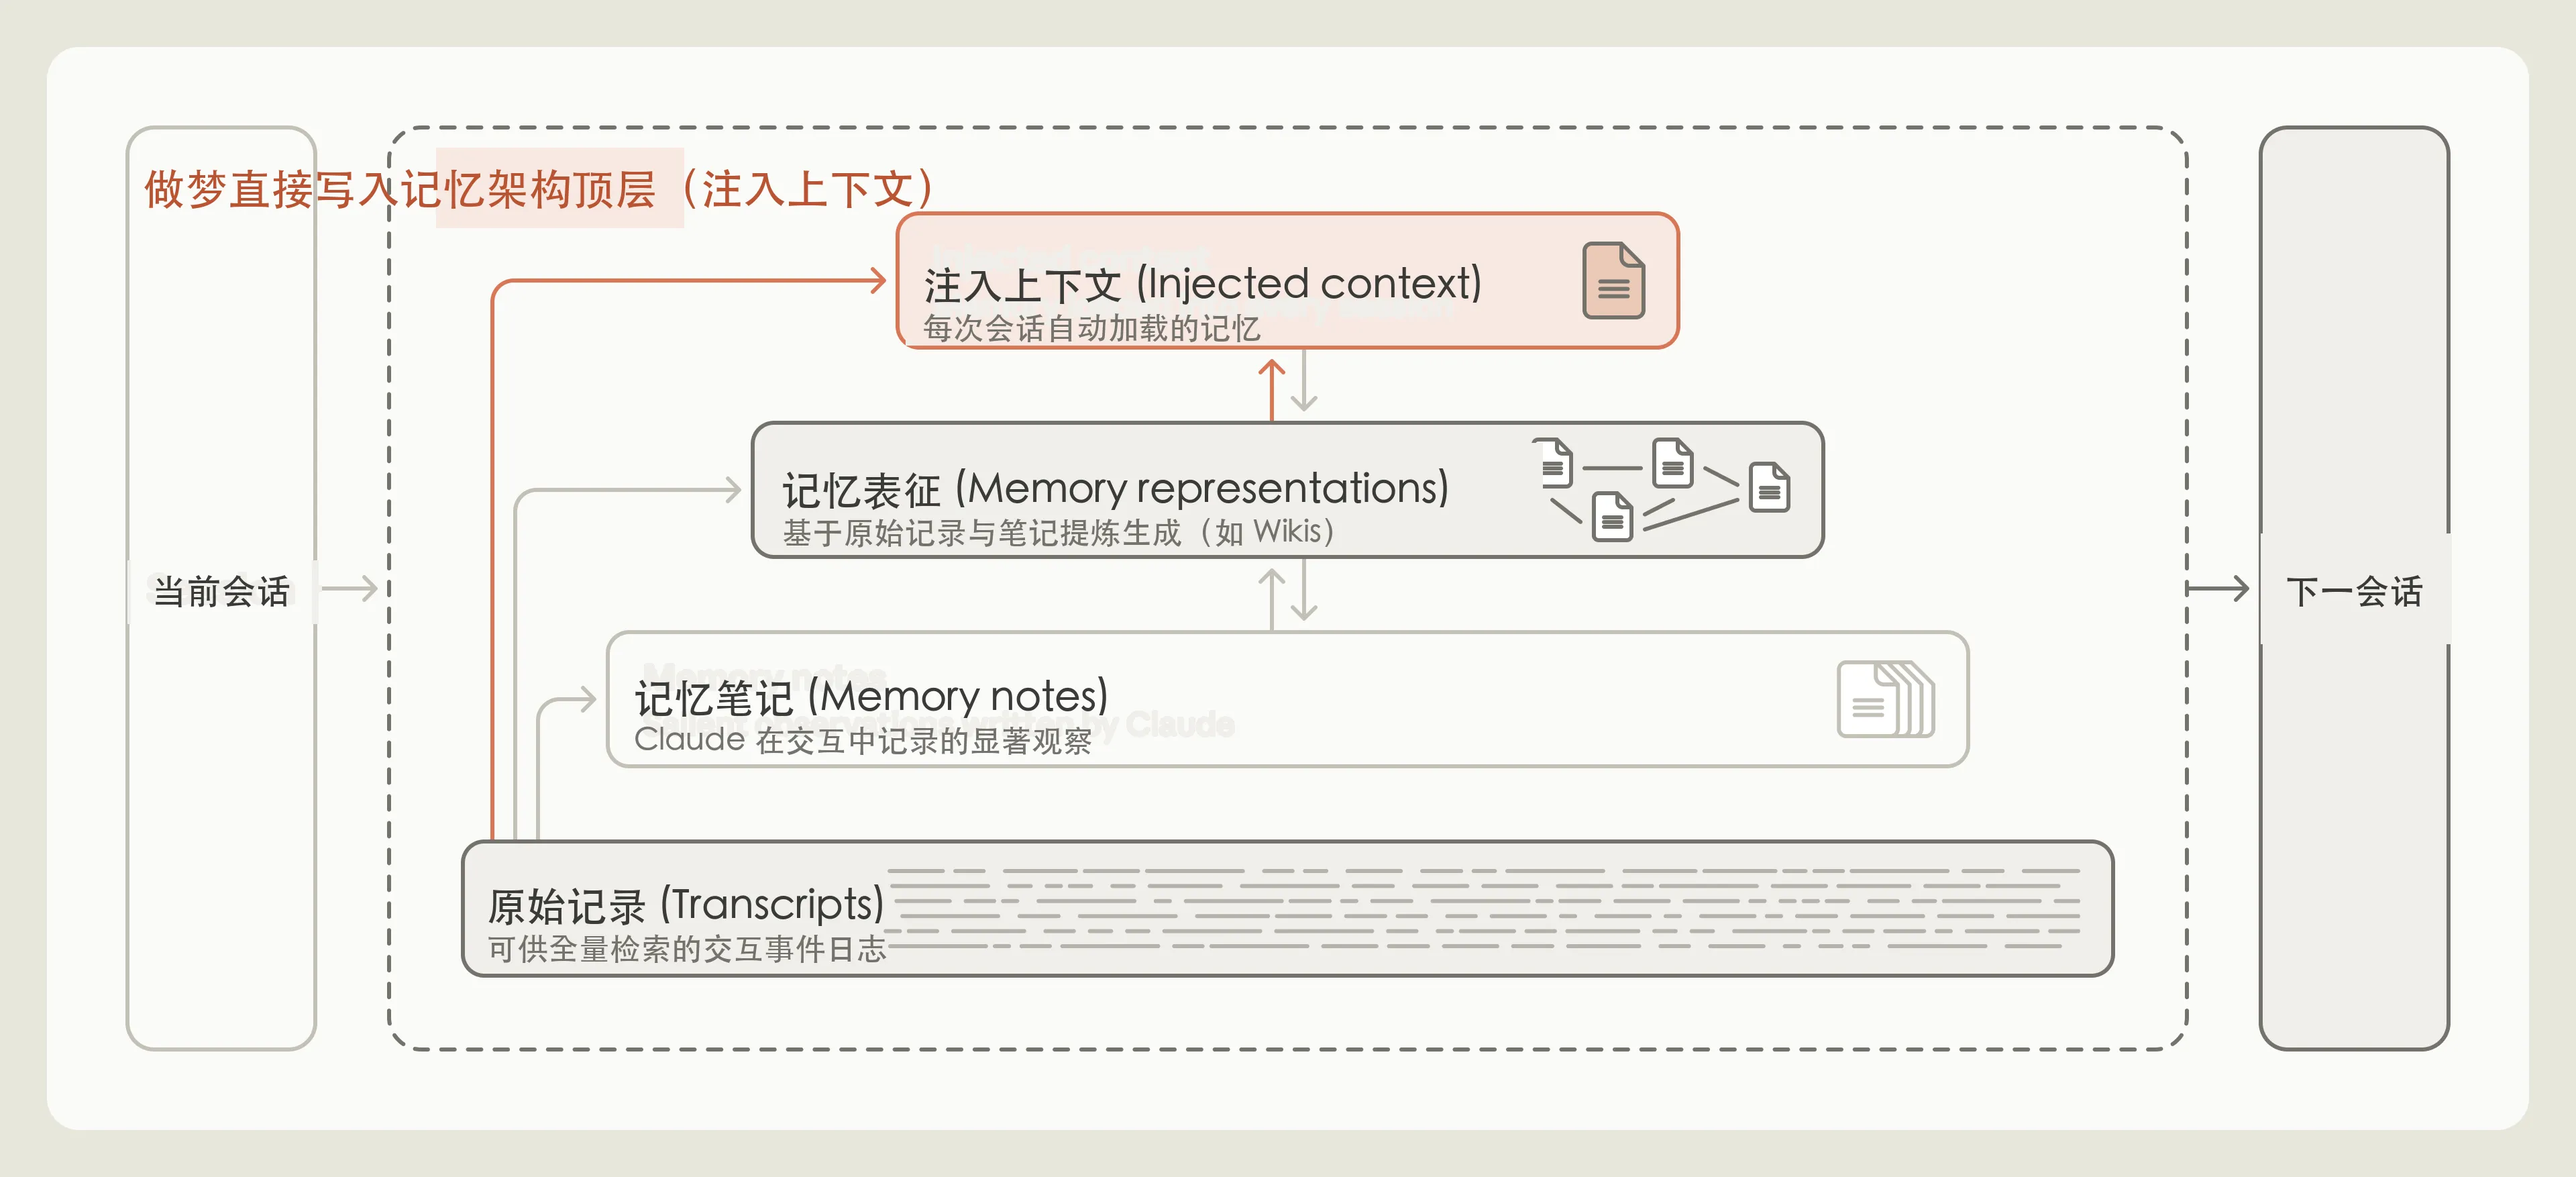
图 13:“做梦”可以直接写入记忆金字塔的顶层。注入上下文(Injected context)在每次会话启动时预先载入,而其下方的各层则在 Claude 需要时按需读取或搜索。
离线做梦可以针对特定目标聚焦记忆 (Focusing memory on specific goals)
原文: Dreaming can also shape how memory grows. An assistant like Claude Duet, for example, often benefits from having memories that are organized around the person it’s helping, and dreaming can be tuned to build memory in service of a particular goal.
离线整合还能塑造记忆的演进方向。例如像 Claude Duet 这样的个人助理,通常需要围绕它所服务的人建立专门的用户记忆,此时我们可以针对性地调优离线整合,使其专为特定目标沉淀记忆。
原文: The instructions that guide how memory grows differ by task and tell Claude what information actually matters. For example, one task in the LAB benchmark simulates a company acquisition and provides a set of contracts. The brief is graded on whether it correctly describes the contract terms.
引导记忆演化的指令因任务而异,其作用是告诉 Claude 究竟什么信息才是真正关键的。例如,LAB 基准测试中的一项任务模拟了公司并购并提供了一套合同,该任务的法律摘要是依据其对合同条款描述的准确性来进行评分的。
原文: We started with basic instructions for generating the wiki that didn’t tell Claude how to use the wiki. This task relied heavily on contract terms. While the wiki was being built, several agents wrote to a shared table of contract terms at the same time (Figure 14, left).
我们最初使用的是构建 Wiki 的基础通用指令,并未对 Claude 规定具体该如何使用 Wiki。这项任务高度依赖准确的合同具体条款。在最初构建 Wiki 时,多个智能体同时向一个共享的合同条款汇总表中写入内容(见图 14 左侧)。
原文: How many graded contract facts made it into the wiki, before and after instructions changed. Left: several agents writing to one shared page; 41 of 57 facts survived. Right: one agent per contract, each writing its own page and quoting terms word for word; 57 of 57 facts survived.
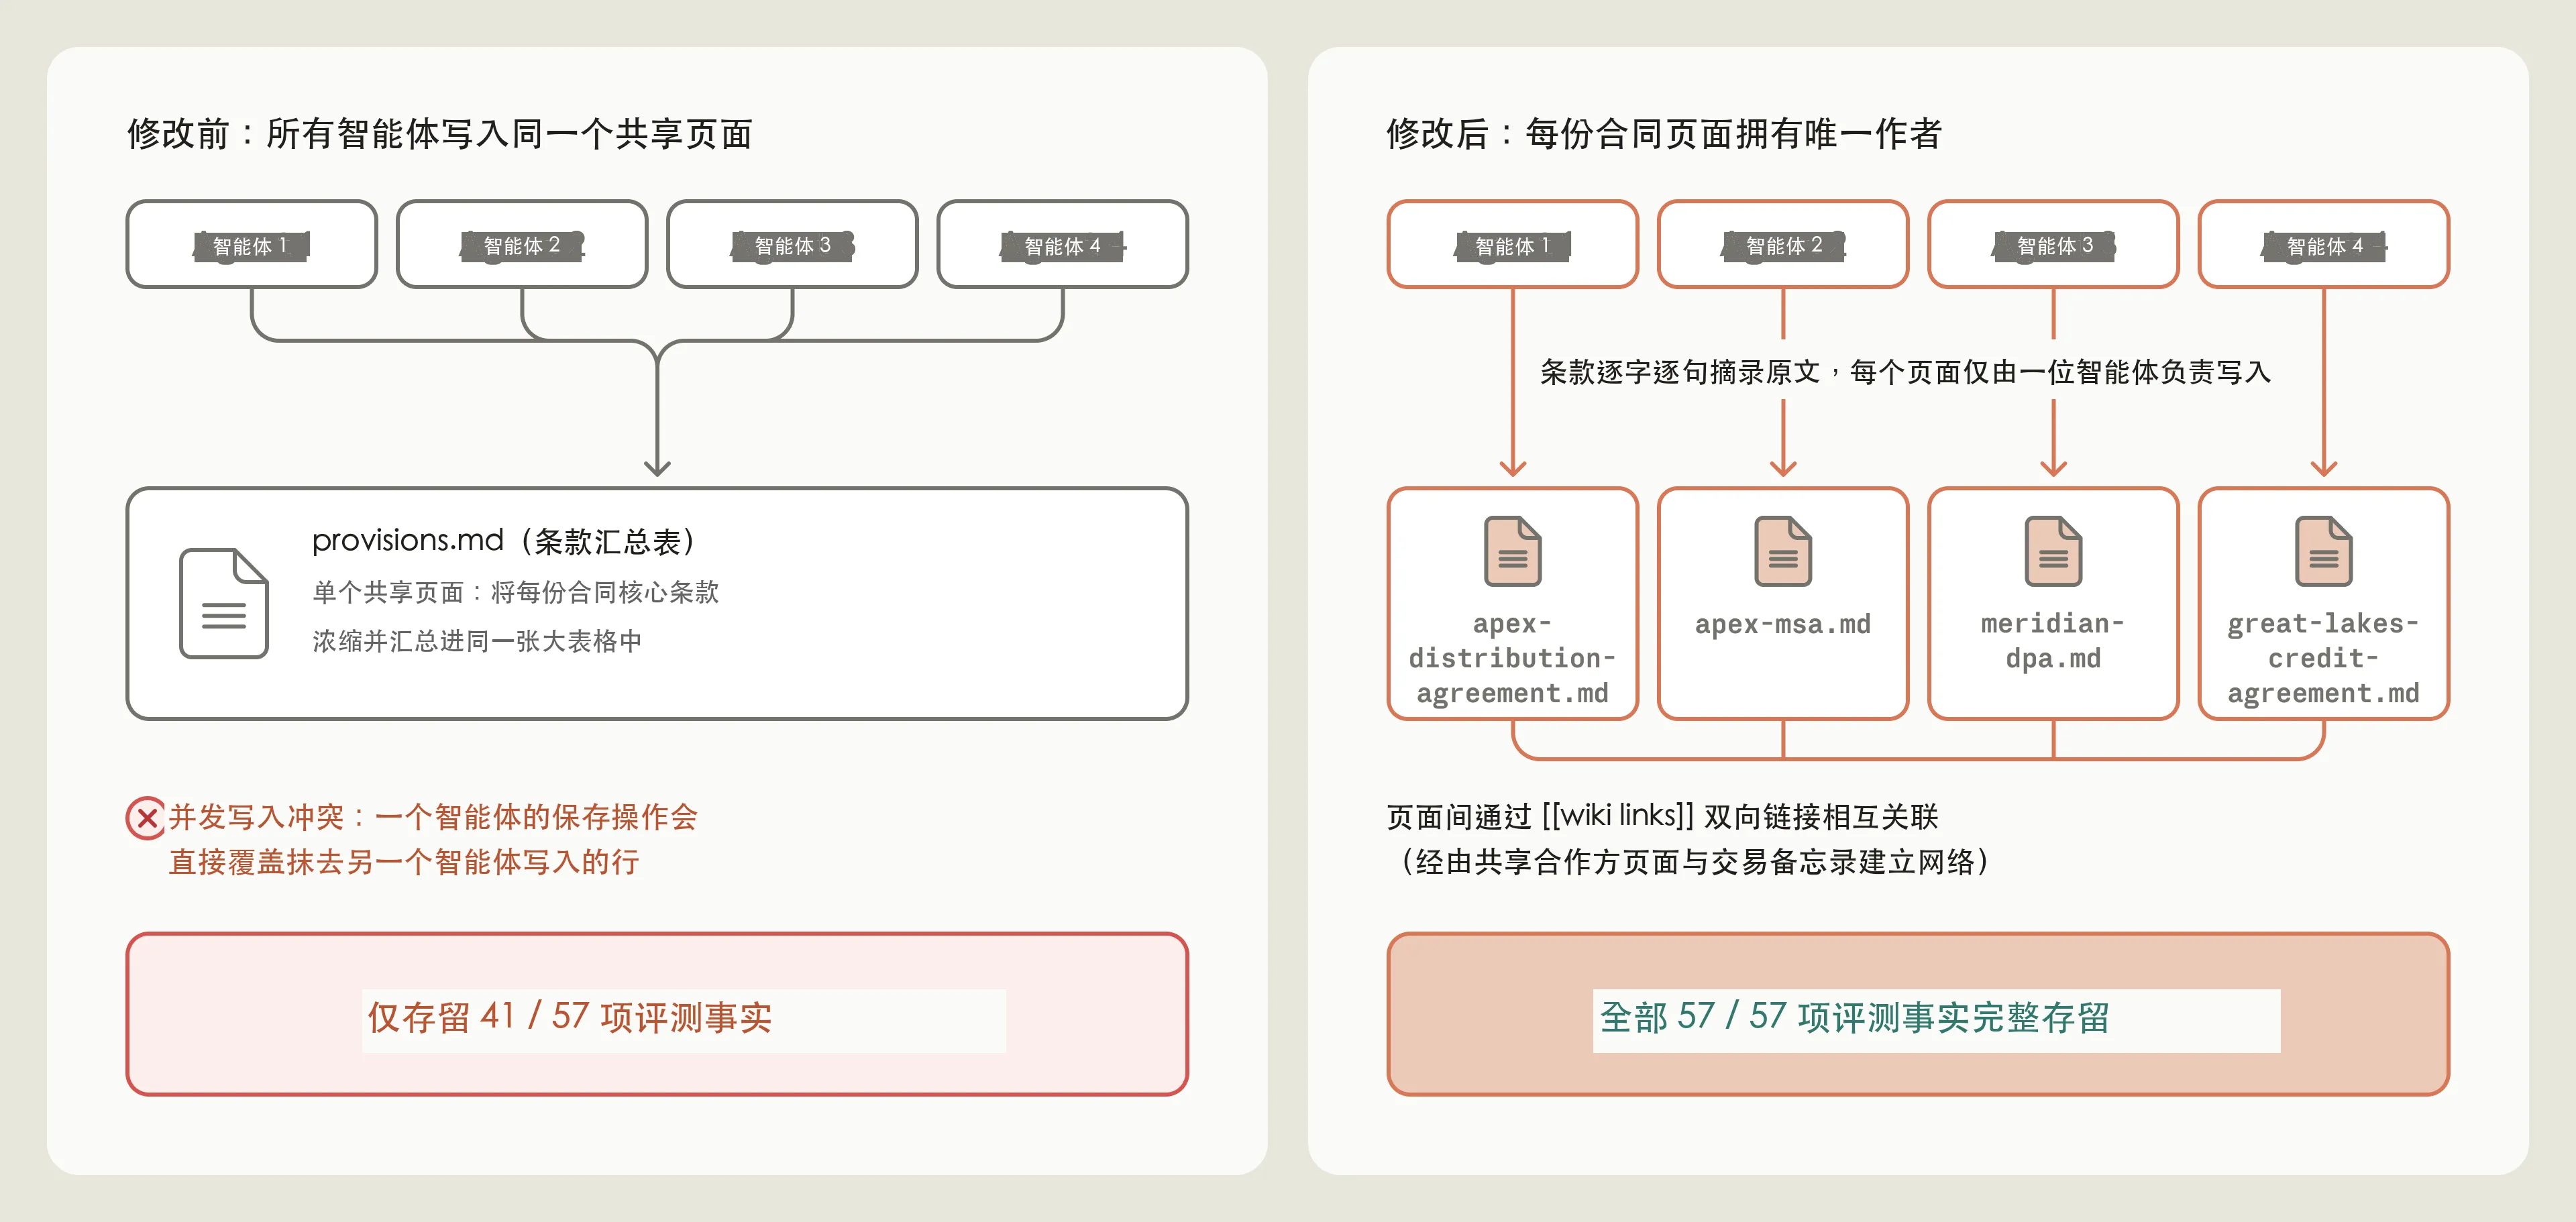
图 14:指令迭代前后,成功写入 Wiki 的评测合同事实存留数量。左侧:多名智能体并发写入同一个共享页面,57 项事实中仅存活 41 项。右侧:每份合同由一名智能体独立负责页面并逐字摘录条款,57 项事实全部完整存留。
原文: The result was a wiki that was missing key facts. When we graded a brief generated from the wiki, Claude had included only 41 of the 57 facts (72%). When we looked at what had gone wrong, we found that the shared table summarized the contract terms poorly and was missing some of them altogether, because agents had overwritten one another’s work.
结果导致 Wiki 遗漏了大量核心事实。当我们对基于该 Wiki 生成的法律摘要进行评分时,Claude 仅命中了 57 项事实中的 41 项(达标率 72%)。深入分析错误原因后我们发现,共享表格对合同条款的总结十分拙劣,有些条款完全缺失,原因在于不同智能体在并发保存时互相覆盖了彼此的工作。
原文: The contract terms were the most important part of the wiki, but the instructions didn’t say that. To find better instructions, we ran a loop in which Claude reflected on its failures, proposed a change to the instructions, and rebuilt the wiki. This loop allowed Claude to discover how important it was to follow the contract terms, and it rewrote the instructions for building the wiki accordingly.
合同条款明明是该 Wiki 最关键的核心,但初始指令并未强调这一点。为了找到更优的指令规范,我们运行了一个让 Claude 自我反思的优化闭环:Claude 反思失败原因 → 提出指令修改建议 → 重新构建 Wiki。这一闭环让 Claude 领悟到了精准保留合同条款的决定性意义,并据此重写了构建 Wiki 的系统指令。
原文: Each contract got its own page in the wiki, written by a single agent, which quoted the terms word for word rather than summarizing them into a shared table. When we graded the brief generated from this improved wiki, 100% of the criteria could be met, up from 72%.
在新的方案中,每份合同在 Wiki 中都拥有独立专属页面,由单个智能体独立撰写,并且严格逐字逐句摘录条款原文,而不是将它们模糊概括进一个共享大表中。当我们再次对根据这套改进版 Wiki 生成的摘要进行评分时,评测指标满足率从 72% 直接飙升至 100%。
离线做梦可以填补跨会话断链 (Healing gaps and dead links)
原文: When Claude writes memory notes, it sees only the context in that particular session. Dreaming can search across many sessions to find common patterns or correct common mistakes.
当 Claude 在单次会话中撰写记忆笔记时,它所能感知的仅限于该特定会话内的即时上下文。而离线整合则能横跨诸多历史会话进行大范围检视,发现跨会话的共性规律,或纠正普遍存在的系统性疏漏。
原文: When building the wikis for the LAB benchmark (as an example, see Figure 14), sometimes Claude would link to pages that hadn’t yet been created. A second dreaming pass closed many of these gaps. On one task (Figure 15), dreaming found nine links to a missing page in the wiki and repointed them to an existing page for the same document. It also added three new pages, including an index, to improve the wiki.
在为 LAB 基准构建 Wiki 时(参见图 14),Claude 有时会在页面中添加指向尚未创建页面的死链接。第二次离线整合遍历成功填补了许多此类空缺。在某项任务中(见图 15),离线整合扫描发现了 9 处指向 Wiki 中不存在页面的死链,并自动将它们重定向到了已存在的对应文档页面上;同时还新增了 3 个全新页面(包括一个全局索引页),极大改善了 Wiki 的连贯性与完整度。
原文: The wiki before and after a second dreaming pass.
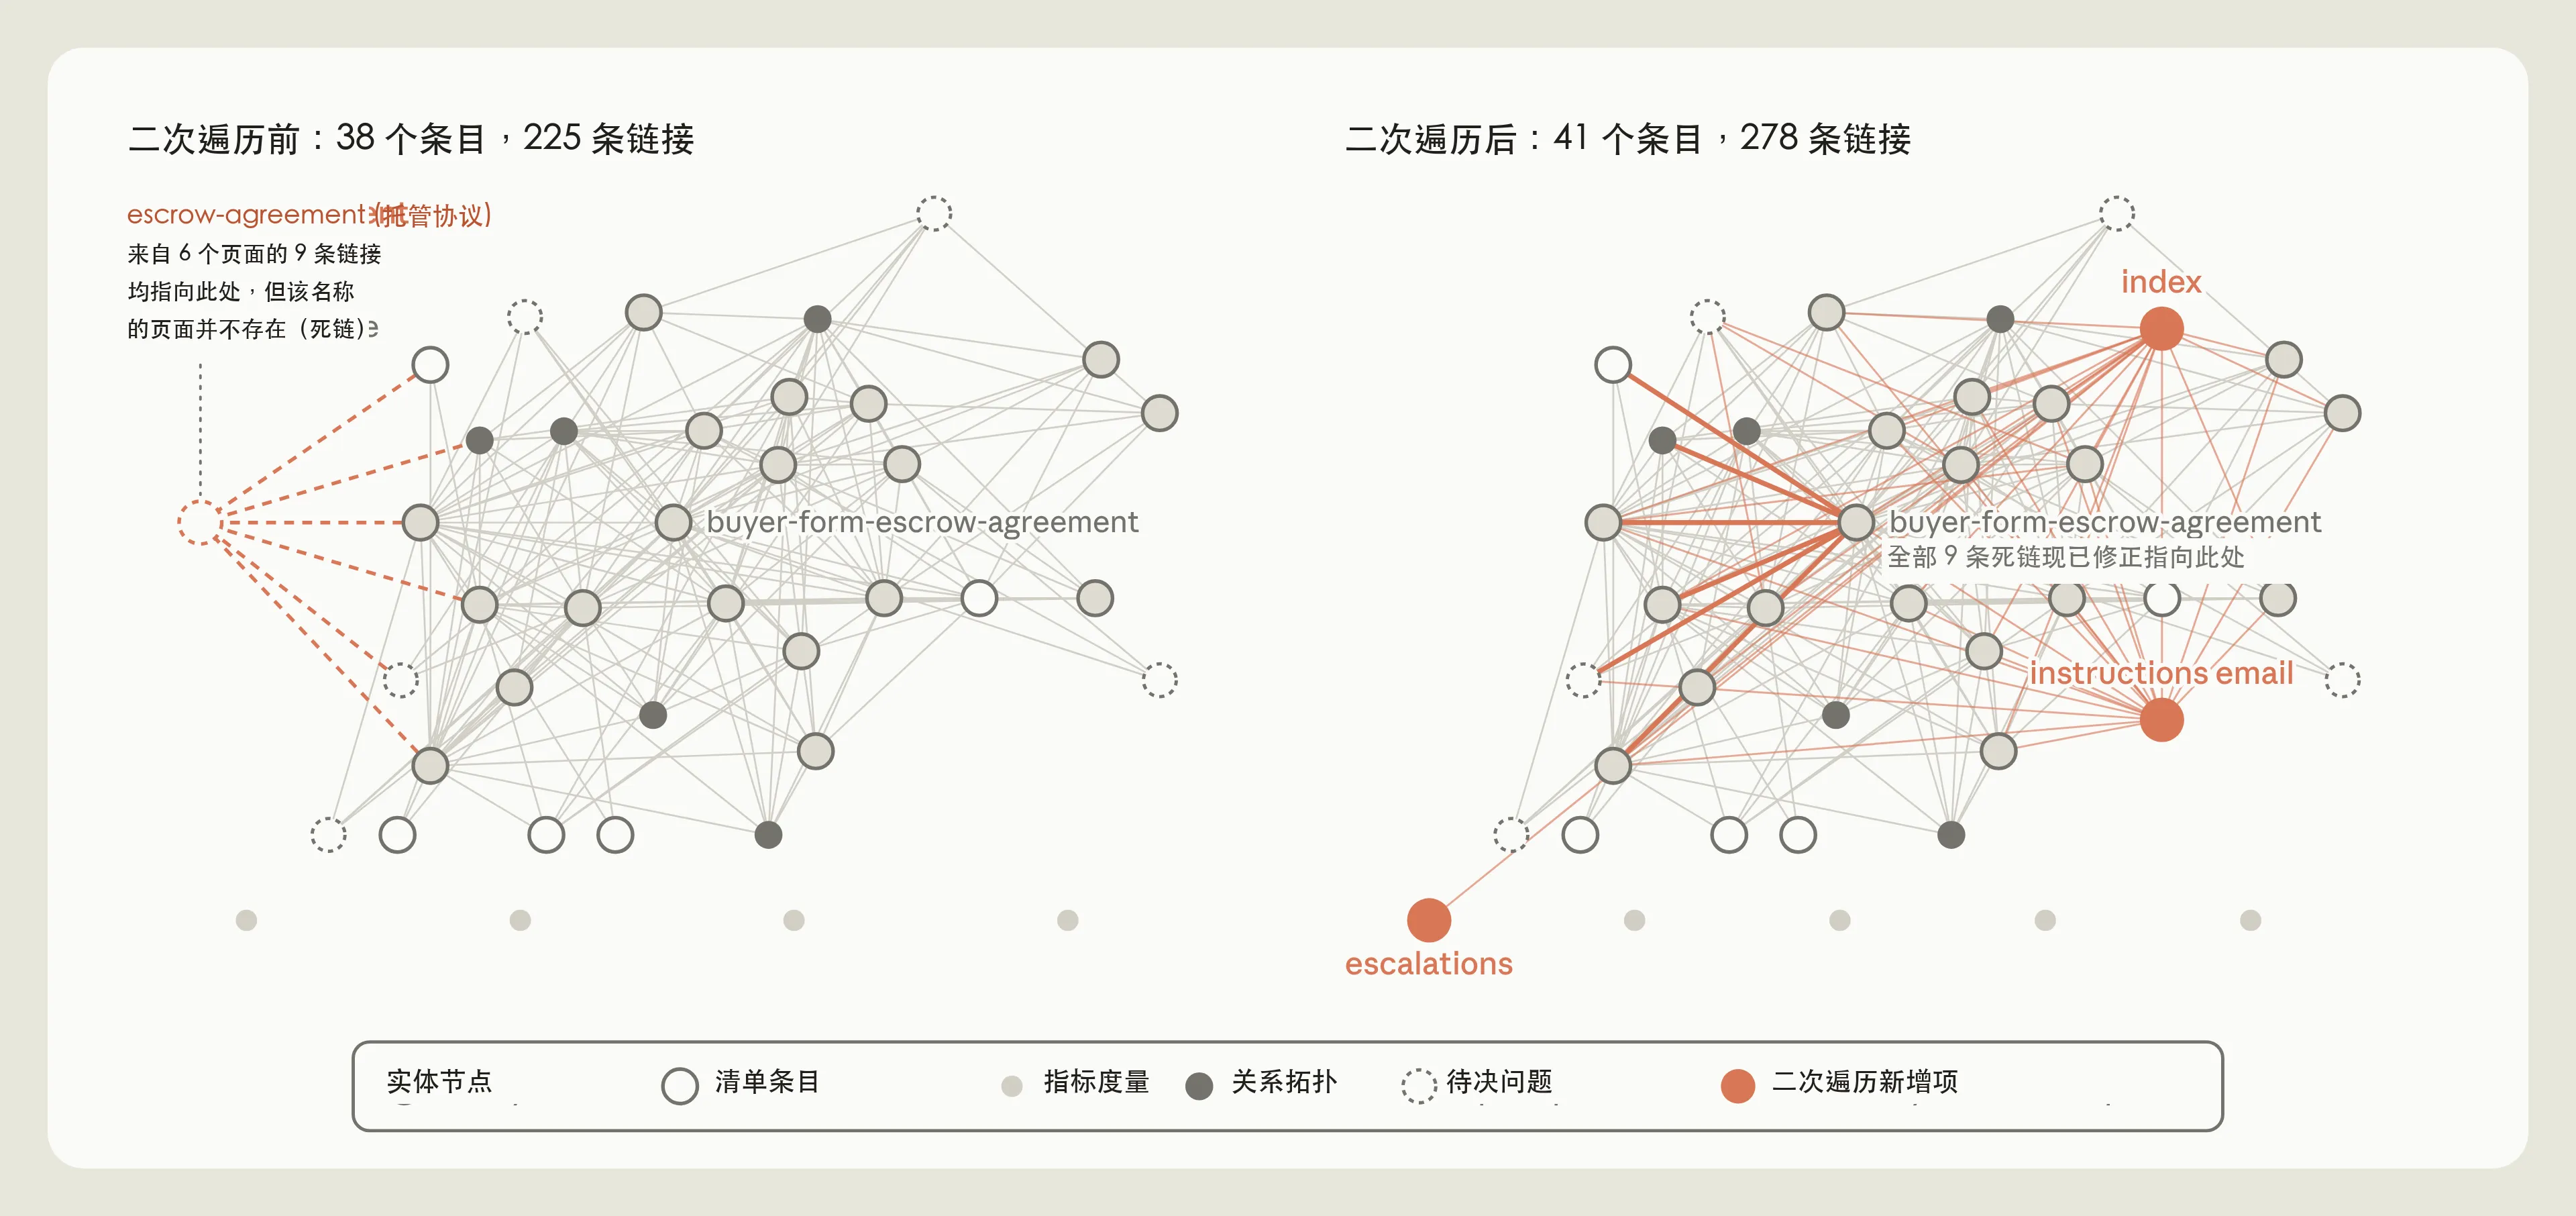
图 15:经历二次“做梦”遍历前后的 Wiki 维基拓扑修复对比。
后向思考,前向展望 (Thinking backward, looking forward)
原文: There are many open questions about how to design memory systems for agents. One is when Claude should create memory. When Claude works on a task, it can write to a memory store (e.g., a folder, file, or database), capturing salience at the source and making important details immediately available for future turns or sessions. But logging notes in the moment inevitably draws Claude’s attention away from its main task. In contrast, dreaming can push memory creation to the background, but any outputs from dreaming may not be immediately accessible to Claude.
在如何为智能体设计记忆系统这一命题上,目前仍有许多开放性问题等待探索:第一,Claude 究竟应当在何时生成记忆?当 Claude 在执行任务时,它可以实时写入记忆存储(例如文件夹、文件或数据库),在第一现场捕捉显著信息,使关键细节能立即在后续对话轮次或会话中生效。但不可避免的是,在当下记录笔记会分散 Claude 投入到核心任务中的注意力。与此相反,离线整合虽然能将记忆沉淀转移到后台运行,但离线生成的知识却无法即刻反馈给当前的实时操作。
原文: Another question is how to keep memory reliably up to date. Claude can make incorrect predictions or write rules to memory that are wrong from the start. Memory can also drift and become irrelevant as the environment changes. Dreaming is one way to fix these mistakes (Figure 8), but it requires compute. Directing Claude to continuously check all its memories might not be practical. It may be important instead to focus dreaming on information that’s likely to change or to carefully tune the cadence of dreaming (e.g., based on how often memories are accessed).
第二,如何确保记忆能够可靠地保持最新?Claude 可能会做出错误的预测,或者从一开始就将不正确的规则写入记忆。随着外部环境的变迁,原本正确的记忆也可能会发生偏移并逐渐失效。“做梦”是修正这些错误的有效途径(见图 8),但它需要耗费额外的计算资源。让 Claude 盲目无休止地核对所有历史记忆并不切实际。因此,关键在于将离线整合算力聚焦在最可能发生变动的信息上,或者根据记忆被访问的频率来精心调节离线整合的触发周期。
原文: It’s also reasonable to consider transcript search as the foundation of Claude’s memory. Combining representations (e.g., wikis) with search (Figure 10) can sometimes be effective. But Claude needs to use compute to maintain memory representations and make sure they don’t accumulate errors or hallucinations.
第三,如何平衡原始记录检索与高级记忆表征?将原始交互记录(transcript)的检索作为 Claude 记忆的底层基石是合情合理的。将高阶表征(如 Wiki)与搜索机制相结合(见图 10)在很多场景下非常高效。但模型必须消耗算力来持续维护这些结构化表征,确保它们不会随着时间推移积累错误或幻觉。
原文: Even though Claude’s judgment about salience has improved, no model can really know what will happen in future turns. Dreaming gives Claude an opportunity to look backward and use compute to organize its memory, correct mistakes, and maintain representations that allow future sessions to access memory more readily. Memory systems will evolve as Claude gets more capable, and we still have a lot to learn about designing Claude’s memory systems.
尽管 Claude 对显著性的辨别判断力已今非昔比,但没有任何模型能够真正洞悉未来的所有交互。“做梦”(离线整合)赋予了 Claude 一个“向后看”的契机:利用后台计算资源梳理组织记忆、修正过往偏差,并维系高阶表征,让未来的会话实例能够更敏捷、更精准地调用经验。随着 Claude 底座能力的持续进阶,智能体记忆系统也将不断演化,关于如何构建真正高效的智能体记忆,我们仍有广阔的天地需要探索。
原文: See our cookbooks for getting started with dreaming and knowledge wikis.
(关于开始使用离线整合与知识维基的实战教程,请参阅我们的 Cookbooks 指南。)
作者与致谢 (Authors & acknowledgements)
原文: Written by Lance Martin, a member of our Engineering team. Editorial guidance from Caitlin Love, Tom Chivers, Rebecca Hiscott, Jake Eaton, Blake Wilson. Thanks to Barry Zhang, Theodora Chu, Daliang Li, Mahesh Murag, Jake Noble, Ravi Trivedi, Tina Vachovsky, Brad Abrams, Henry de Valence, Jeremy Fox, Matt Bell, Allen Li, Chris Gorgolewski, Eugene Yan, Artur Renault, Wei Zhang, and Kevin Chen for helpful discussions and contributions; David Hershey for Claude Plays Pokémon. Illustrations by Monika Tuchowska.
致谢
- 本文作者:Lance Martin(Anthropic Engineering)
- 编辑指导:Caitlin Love、Tom Chivers、Rebecca Hiscott、Jake Eaton、Blake Wilson
- 特别鸣谢:感谢 Barry Zhang、Theodora Chu、Daliang Li、Mahesh Murag、Jake Noble、Ravi Trivedi、Tina Vachovsky、Brad Abrams、Henry de Valence、Jeremy Fox、Matt Bell、Allen Li、Chris Gorgolewski、Eugene Yan、Artur Renault、Wei Zhang 和 Kevin Chen 的有益探讨与贡献;感谢 David Hershey 提供的 Claude Plays Pokémon 项目。
- 插图设计:Monika Tuchowska